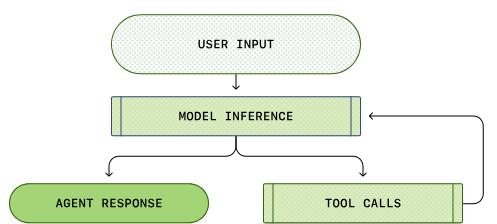
(Image source: OpenAI codex agent post)
(图片来源:OpenAI 的 codex 智能体文章)
Lilian Weng · 原文发表于 2026-07-04 · 整理于 2026-11-06
Harness Engineering for Self-Improvement · 阅读原文
左英文、右中文,逐段对齐。非官方译文;图内文字保留原样,点击图片可查看原始尺寸。
这篇文章把自我改进的视角,从模型权重扩展到了模型周围的运行系统。Harness 不只是提示词模板,而是决定智能体如何规划、调用工具、管理上下文与持久状态、执行评测的运行框架。改进这个框架,同样可能提升智能体完成任务和开展研究的能力。
作者先介绍工作流自动化、文件系统记忆、子智能体与后台作业等基础模式,再讨论优化对象如何从提示词扩展到结构化上下文、工作流、框架代码,乃至优化器本身。重点不是堆叠更多规则,而是让改进过程可执行、可观察、可检验。
框架发生了更新,不等于能力获得了提升。自我改进需要可靠的评测信号、可回看的执行轨迹、留出测试,以及对失败案例和长期维护成本的关注。否则,系统可能只是更会利用当前评分器的漏洞。
早期智能体常被概括为模型、记忆、工具、规划和行动的组合。文章进一步强调工作流、权限控制、评测与持久状态管理。设计应简单、通用,让模型利用既有的软件工程知识,而不是不断增加只能应付个别案例的启发式规则。
工作流通过规划、执行、观察、测试和改进形成循环;文件系统承载日志、实验记录、差异和历史轨迹,避免所有内容都塞进上下文;子智能体与后台作业允许并行探索,同时要求清晰的启动、状态检查、取消和结果合并机制。这些设计使长任务能够检查、恢复和复盘。
文章按上下文工程、工作流设计、自我改进框架、进化搜索与模型权重联合优化展开。ACE 将上下文维护为可增量更新的经验条目;MCE 区分上下文管理机制和具体内容;Meta-Harness 将运行框架代码及其优化方式纳入搜索。它们把获取好答案的方法本身变成可以改进的对象。
工作流自动设计和进化式程序搜索依赖候选方案生成、评估、选择与经验复用。自动化让尝试更多方案成为可能,也让验证器质量、可复现环境和搜索多样性更加重要。负面结果、失败轨迹和历史记录可以帮助避免重复走入死路。
作者讨论了评测器能力不足、标准模糊、记忆生命周期、负面结果利用、多样性坍缩和奖励投机。框架更新应与框架收益分开衡量;评测器和权限控制应尽可能位于被优化的循环之外,并配合留出测试、轨迹审计及关键节点的人类判断。
短期通过测试不代表长期维护良好。代码所有权、迁移成本、向后兼容和未来调试负担,很难被单次沙箱任务的奖励充分捕捉。作者主张让人类在合适的抽象层级和时间点提供监督。文末的 PaperBench、CORE-Bench、ScienceAgentBench、RE-Bench、MLE-bench 和 KernelBench,可作为继续理解科研与工程能力评测的入口。
The concept of recursive self-improvement (RSI) dates back to I. J. Good (1965), where he defined an “ultraintelligent machine” as a system that can surpass humans in all intellectual activities and design better machines to improve itself. Yudkowsky (2008) used the phrase “recursive self-improvement” for a specific feedback loop: an AI uses its current intelligence to improve the cognitive machinery that produces its intelligence.
所谓递归自我改进(RSI)这一概念可追溯至 I. J. Good (1965),他在其中将“超智能机器”定义为一种能够在所有智力活动中超越人类,并通过设计更好的机器来改进自身的系统。Yudkowsky (2008) 用“递归自我改进”这一表述来描述一种特定的反馈循环:AI 利用其当前的智能,改进产生其智能的认知机制。
This feedback loop in modern AI may indicate the model rewriting its own weights directly, or more broadly the model improves the training pipeline and the deployment system, which in turn enables a better successor model with improved performance across economically valuable tasks. The speed of research development in AI has been shown to drastically accelerated in frontier labs (Anthropic; OpenAI).
I explicitly mention “deployment system” because the layer between the raw model and the real-world context seems to be as important as the model’s raw intelligence (i.e. the evals right after pretraining). Harnesses are important components of AI deployment, as shown by successful coding agent products such as Claude Code and Codex. A harness is the system surrounding a base model that orchestrates execution and decides how the model thinks and plans, calls tools and acts, perceives and manages context, stores artifacts, and evaluates results.
我特意提到“部署系统”,是因为原始模型与现实世界情境之间的这一层,似乎与模型的原始智能(即预训练刚结束时的评测所体现的智能)同样重要。运行框架是 AI 部署的重要组成部分,Claude Code 和 Codex 等成功的编程智能体产品就体现了这一点。运行框架是围绕基础模型构建的系统,负责统筹执行,并决定模型如何思考与规划、调用工具与采取行动、感知与管理上下文、存储产物,以及评测结果。
This one post will focus on research around harness engineering and how it contributes to RSI. Much recent work on auto-research, self-improving agents, and evolutionary program search can be organized around this question. Other work on model self-play, synthetic data, test-time training and a broader theme of continual learning also matches the RSI vision (e.g. Yuan et al. 2024, Chen et al. 2024), Zhao et al. 2025, Choi et al. 2026)) but they will not be the focus of this post.
本文将聚焦于运行框架工程相关研究,以及它如何促进 RSI。近期许多关于自动化研究、自我改进智能体和进化式程序搜索的工作,都可以围绕这一问题来梳理。其他有关模型自我对弈、合成数据、测试时训练,以及更广泛的持续学习主题的工作,也符合 RSI 的愿景(例如 Yuan et al. 2024, Chen et al. 2024), Zhao et al. 2025, Choi et al. 2026)),但它们不是本文的重点。
Compared with early agent frameworks, “agent = LLM + memory + tools + planning + action”, harnesses engineering additionally include workflow design (e.g. loop engineering), evaluation, permission controls, and persistent state management. It is no longer only prompt templates, but closer to runtime and software system design: how the model observes, acts, memorizes, checks itself, and improves.
相比于早期的智能体框架,即“智能体 = LLM + 记忆 + 工具 + 规划 + 行动”,智能体运行框架工程还包括工作流设计(例如循环工程)、评测、权限控制和持久状态管理。它不再只是提示词模板,而是更接近运行时和软件系统设计:模型如何观察、行动、记忆、自检和改进。
The design should be deliberately simple and generic to enable generalization, likely with reference to existing software engineering practices to benefit from prertaining knowlege. There is also a strong analogy between operating systems and harnesses. Similar to an OS, a harness should encapsulate complicated logic while keeping the interface simple. Meanwhile, configs, tool interfaces and other protocols may gradually become standardized across the industry.
设计应有意保持简单和通用,以实现泛化,并且可能需要参考现有的软件工程实践,以利用预训练知识。操作系统与智能体运行框架之间也有很强的相似性。与操作系统类似,运行框架应封装复杂逻辑,同时保持接口简单。与此同时,配置、工具接口及其他协议可能会逐渐在整个行业实现标准化。
Defining a workflow in which the model can operate, test, and iterate is a key design for automation. Karpathy’s autoresearch repo (https://github.com/karpathy/autoresearch) is a clean example of how such a workflow can be constructed. A common workflow follows a goal-oriented loop of plan, execute, observe/test, improve, and execute again until the goal is achieved. The process may trigger proactive requests to users for clarity in task specification or execution preference.
定义一个让模型能够在其中操作、测试和迭代的工作流,是实现自动化的关键设计。Karpathy 的 autoresearch 仓库(https://github.com/karpathy/autoresearch)清晰地展示了如何构建这样的工作流。常见的工作流遵循一个以目标为导向的循环:规划、执行、观察/测试、改进,再次执行,直到目标达成。在此过程中,系统可能会主动请求用户澄清任务说明或执行偏好。
The workflow graph also emphasizes the model analyzing its own trajectories and failure cases and then iterating on its progress through an “agent runtime” rather than a static prompt template.
该工作流图还强调,模型会分析自身的轨迹和失败案例,然后通过“智能体运行时”而非静态提示词模板,迭代推进任务。
A recurring pattern in long-horizon agent systems is simple control over rich states and artifacts. A harness should not carry the entire workflow and all logs in context; instead, it should keep durable state in files. In long-horizon agentic rollout, artifacts such as experiment logs, code diffs, paper summaries, error traces, and past rollout trajectories often grow much longer than the context window that the model has trained for.
在长程智能体系统中,一种反复出现的模式是对丰富的状态和产物进行简单控制。运行框架不应将整个工作流和所有日志都放在上下文中;相反,它应将持久状态保存在文件中。在长程智能体轨迹展开过程中,实验日志、代码差异、论文摘要、错误跟踪记录和过去的展开轨迹等产物,其长度往往会增长到远超模型训练时所用上下文窗口的程度。
Learning how to read, write, and edit the file system (commonly via bash commands) is a foundation skill for LLMs, and thus managing persistent memory in the simple form of files naturally benefits from improvements in core model capability.
学习如何读取、写入和编辑文件系统(通常通过 bash 命令)是 LLM 的一项基础技能,因此,以文件这种简单形式管理持久记忆,自然会受益于核心模型能力的提升。
A harness can spawn multiple subagents to execute in parallel and monitor backend jobs. This is useful when the main agent needs to search multiple hypotheses, run experiments concurrently, or delegate isolated subtasks without polluting the main context. The parent agent then needs a small process manager: launch jobs, inspect logs, cancel failed runs, and merge results back into the main agent thread.
运行框架可以创建多个子智能体来并行执行任务,并监控后台作业。当主智能体需要搜索多种假设、并发运行实验,或在不污染主上下文的情况下委派独立子任务时,这种机制很有用。此时,父智能体需要一个小型进程管理器:启动作业、检查日志、取消失败的运行,并将结果合并回主智能体线程。
The key design choice is to make parallelism explicit and inspectable. If subagent outputs only live in a transient chat context, they quickly become obselete and hidden. If they are stored as files, logs, and status records, the model can recover after interruptions and reason over its own execution history.
关键的设计选择是让并行执行显式化且可检查。如果子智能体的输出只存在于临时聊天上下文中,它们很快就会过时并变得不可见。如果将其存储为文件、日志和状态记录,模型就能在中断后恢复,并基于自身的执行历史进行推理。
The core interface of mainstream coding agents has become stabilized across Claude Code, Codex, OpenCode, and Cursor-style agents. They commonly use a loop like:
Claude Code、Codex、OpenCode 和 Cursor 类智能体等主流编程智能体的核心接口已趋于稳定。它们通常采用如下循环:
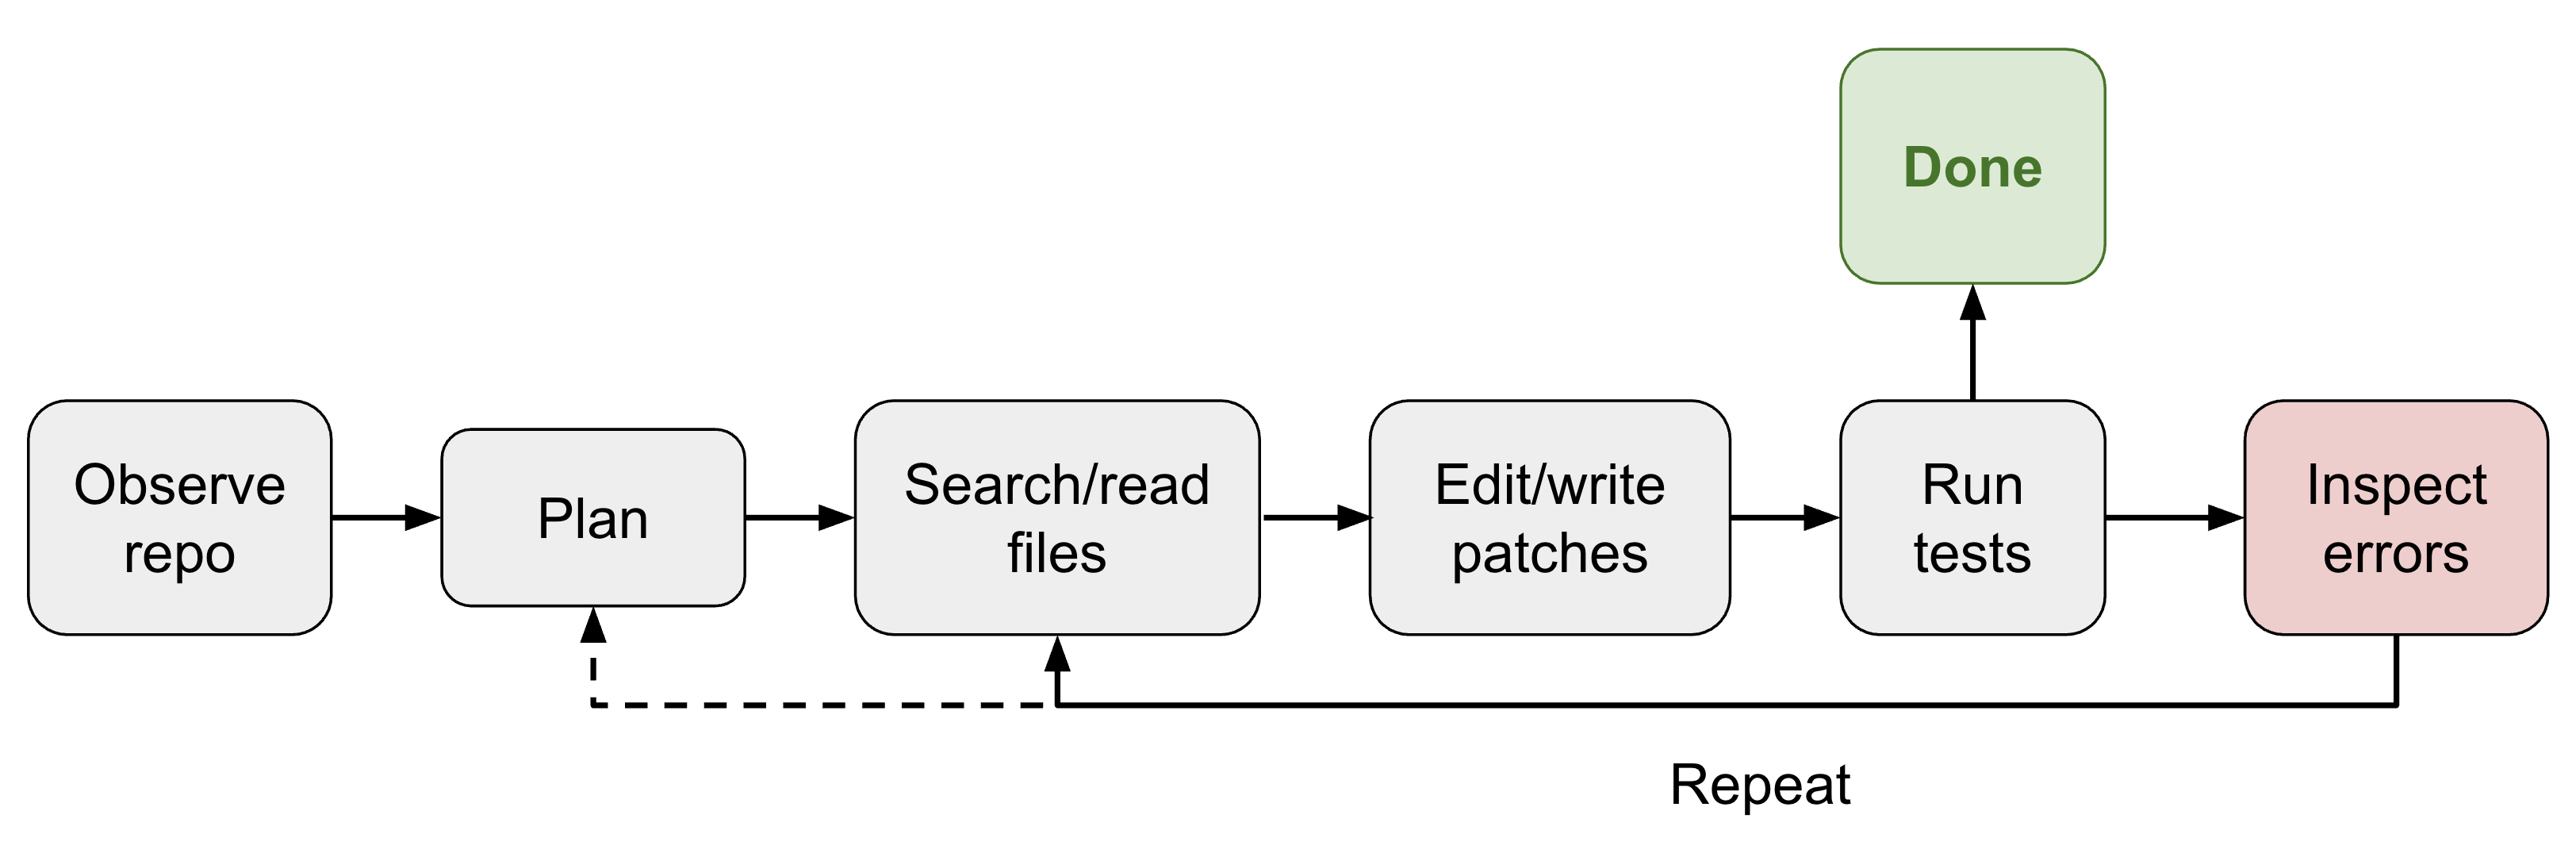
With access to a set of tools, the coding agent is able to develop and debug issues in a given repository, similar to how human developers are equipped with IDEs.
通过访问一组工具,编程智能体能够在给定仓库中进行开发和问题调试,这类似于为人类开发者配备 IDE。
(Not a comprenhensive list; shown for demonstration. Read this if interested.)
(此列表并不全面,仅作演示。如有兴趣,请阅读此文。)
| Group | Tool definitions |
|---|---|
| File system | - File discovery: glob, grep, ls- File read: read, read_many- File modification: write (a whole new file); edit (string exact-match replacement); multi_edit; apply_patch (applies a structured patch/diff) |
| Shell execution | Run commands: bash, PowerShell |
| IO | lsp, git tools like git_status, git_diff, git_commit |
| External context | MCP tools, Skills |
| Web search | web_search, web_fetch, browser tools |
| Artifacts | Read docs, images; generate HTML, images |
| Backend processes | Such as: CronCreate, CronDelete, CronList |
| Agent delegation | Such as: spawn_agent, resume_agent, wait_agent, list_agents, close_agent, interrupt_agent, etc. |
| 分组 | 工具定义 |
|---|---|
| 文件系统 | - 文件查找:glob, grep, ls- 文件读取: read, read_many- 文件修改: write(一个全新的文件);edit(字符串精确匹配替换);multi_edit; apply_patch(应用结构化补丁/差异) |
| Shell 执行 | 运行命令:bash, PowerShell |
| IO | lsp、git 工具,例如 git_status, git_diff, git_commit |
| 外部上下文 | MCP 工具、Skills |
| 网页搜索 | web_search, web_fetch、浏览器工具 |
| 产物 | 读取文档、图像;生成 HTML、图像 |
| 后台进程 | 例如:CronCreate, CronDelete, CronList |
| 智能体委派 | 例如:spawn_agent, resume_agent, wait_agent, list_agents, close_agent, interrupt_agent等。 |
It is hard to forecast how much the future of RSI will rely on harness engineering, but the near-term path of RSI is unlikely to start as a model directly rewriting its weights. My prediction of a practical near-term path is:
很难预测 RSI 的未来会在多大程度上依赖 harness 工程,但 RSI 的近期路径不太可能从模型直接重写自身权重开始。我所预测的一条切实可行的近期路径是:
Eventually it is possible that many harness improvements will be internalized into core model behavior, but the interface with external context and tools should remain. We have seen a softer version of this pattern with prompt engineering: manual prompt tricks became less central as instruction tuning and model reasoning improved, but the need to specify goals, constraints, context, and evaluation did not disappear.
最终,许多 harness 改进可能会内化为模型的核心行为,但与外部上下文和工具交互的接口应该仍会保留。我们已经在提示词工程中见过这种模式较为温和的版本:随着指令微调和模型推理能力的改进,手工设计的提示词技巧不再那么核心,但明确目标、约束、上下文和评测的需求并没有消失.
The progression in the object being optimized in the harness system is roughly: instruction prompts → structured context → workflow → harness code → optimizer code. As the model becomes more intelligent and powerful, we move toward more complex targets and generic methods.
Harness 系统中优化对象的演进大致为:指令提示词 → 结构化上下文 → 工作流 → harness 代码 → 优化器代码。随着模型变得更智能、更强大,我们会转向更复杂的目标和更通用的方法。
Simply appending all the tool responses and model generations into the context can quickly grow out of control as the agentic job horizon increases significantly. Context management is a layer to construct a more structed and concise context for LLM and manage persistant states. There is no doubt that long-context research will keep on making progress but at the moment long-context intelligence and context engineering sometime intertwines.
随着智能体任务跨度显著增加,简单地将所有工具响应和模型生成内容追加到上下文中,会使上下文迅速膨胀到难以控制的程度。上下文管理这一层负责为 LLM 构建更有结构、更简洁的上下文,并管理持久状态。毫无疑问,长上下文研究将持续取得进展,但目前长上下文智能与上下文工程有时会相互交织。
Agentic Context Engineering (ACE; Zhang et al. 2025) treats context as an evolving playbook rather than an increasingly lengthening prompt. It has three components to maintain one context playbook of bullet points, each with an identifier and a description.
智能体上下文工程(ACE;Zhang et al. 2025) 将上下文视为不断演进的操作手册,而非越来越长的提示词。它包含三个组件,用于维护一份由要点条目组成的上下文操作手册,每个条目都有一个标识符和一段描述。
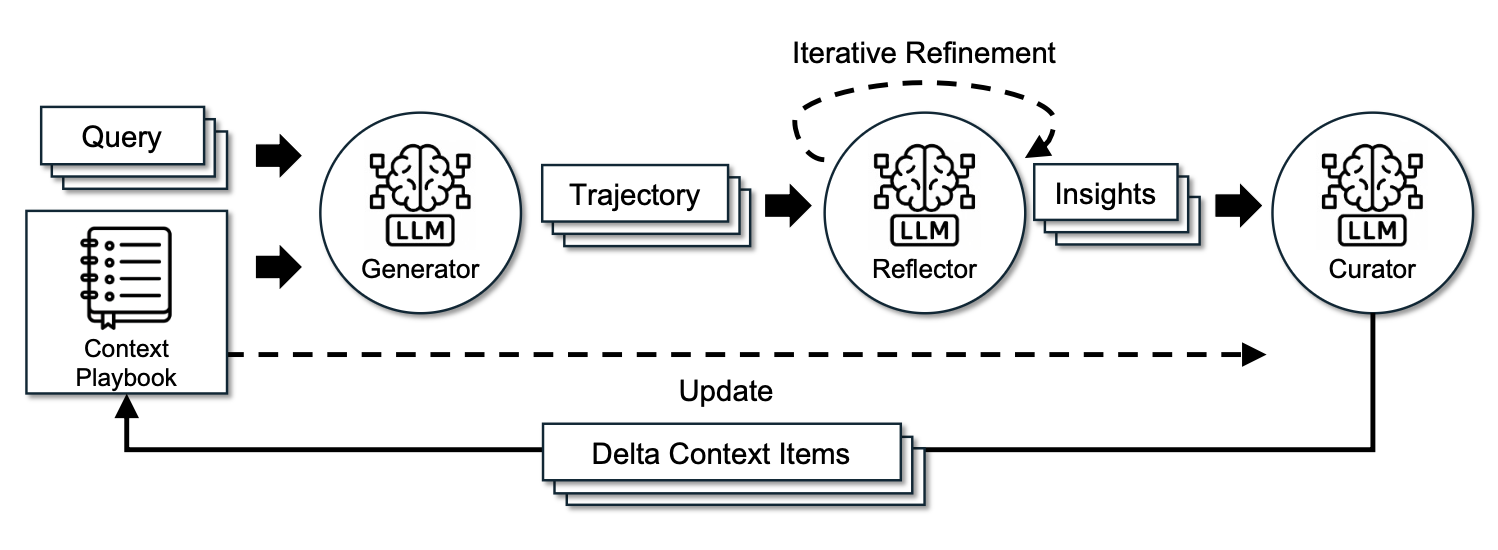
To prevent context collapse and brevity bias during iterative rewrites, one key design choice in ACE is that the curator does not rewrite a full prompt blob. It instead outputs a collection of structured, itemized bullets in the form of (identifier, description), and these bullets are merged into a structured context logbook with deterministic logic. The context items are refined and deduplicated periodically.
为防止迭代重写过程中的上下文坍缩和简短偏好,ACE 的一个关键设计选择是:整理器不会重写整块提示词。相反,它输出一组形式为(标识符,描述)的结构化要点条目,并通过确定性逻辑将这些条目合并到结构化的上下文日志中。上下文条目会定期进行优化和去重。
The fact that ACE learns insights from rollouts helps us move toward self-managed memory, but the update rules and the overall workflow are still handcrafted. To move toward a more self-improving loop, Meta Context Engineering (MCE; Ye et al. 2026) separates the mechanism (how to manage context) from the artifact content (what is in context), running skill evolution at the meta-optimization level and context optimization at the base level.
ACE 从 rollout 中学习见解,这有助于我们迈向自主管理的记忆,但更新规则和整体工作流仍然是手工设计的。为迈向更具自我改进能力的循环,元上下文工程(MCE; Ye et al. 2026) 将机制(如何管理上下文)与产物内容(上下文中包含什么)分离,在元优化层面执行技能演进,在基础层面执行上下文优化。
An MCE skill defines a context function and maps an input to context , where:
一个 MCE 技能 定义了上下文函数 ,并将输入 映射为上下文 ,其中:
The bi-level optimization is to find the best context given skill on the training data, while the outer loop finds the optimal skill that provides the best performance on the validation set:
双层优化在给定技能 的条件下,在训练数据上寻找最佳上下文 ,而外层循环则寻找在验证集上表现最佳的最优技能:
The skill database tracks the history of previous skills, context functions and eval metrics . A meta-level agent performs agentic crossover over prior skills to create a new skill given a task : .
技能数据库记录先前技能、上下文函数和评测指标的历史 。元层级智能体执行智能体式交叉操作,对先前的技能进行组合,以针对给定任务 创建新技能:。
Then a base-level context engineer executes the skill and learns the context function from rollout feedback , guided by the current skill: .
随后,基础层级的上下文工程师执行技能 ,并在当前技能的指导下,从 rollout 反馈 中学习上下文函数:。
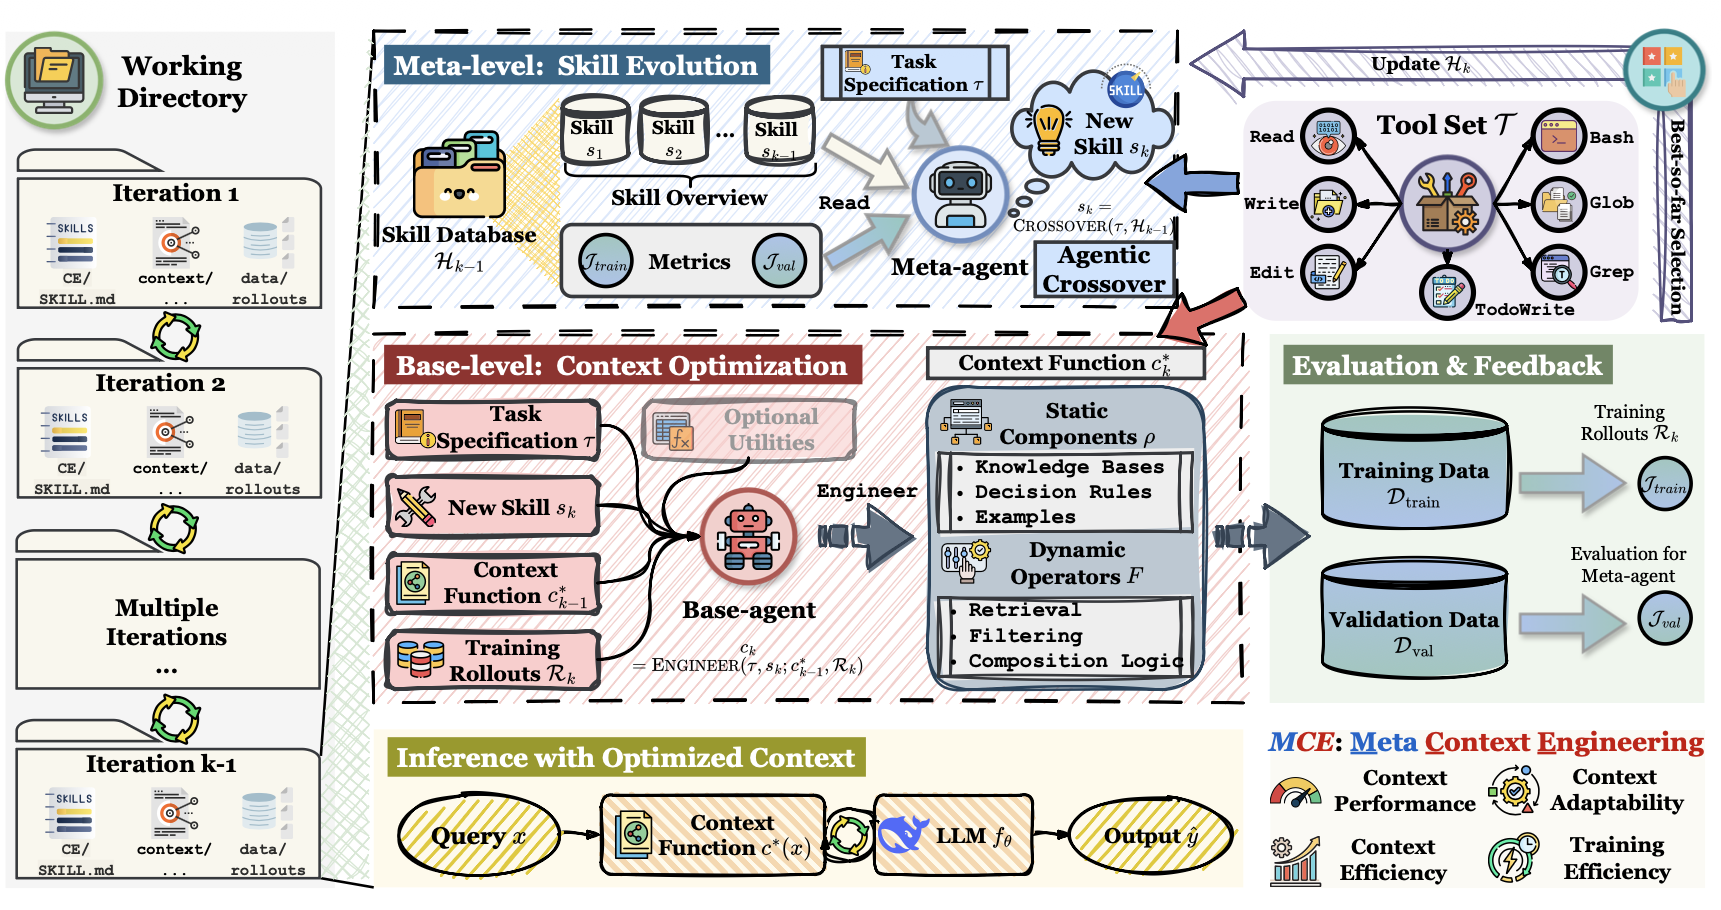
MCE does not enforce a heuristic rule for how to structure context as ACE does. It uses free-form skills to store the most important knowledge for a task, and evolves the skill and the skill-conditioned context iteratively together. Implementation-wise, a context function is instantiated as a collection of files in a dedicated directory, including both static (skill.md) and dynamic (context and data rollouts) components. Both meta-level and base-level optimization are executed in agentic coding envs with a standard tool set,
MCE 不像 ACE 那样强制采用启发式规则来组织上下文。它使用自由形式的技能来存储任务中最重要的知识,并通过迭代共同演进技能及以技能为条件的上下文。在实现上,上下文函数 被实例化为专用目录中的一组文件,其中既包括静态(skill.md)组件,也包括动态(上下文和数据 rollout)组件。元层级和基础层级的优化都在配备标准工具集的智能体编程环境中执行,
Meta-Harness (Lee et al. 2026) moves another level deeper: the optimized object is the code that determines and optimizes what information should be stored, retrieved, and presented to the model. “Meta-” in its name means it is a harness for optimizing harnesses.
Meta-Harness (Lee et al. 2026)又深入了一层:优化对象是代码,这些代码决定并优化应存储、检索哪些信息,以及向模型呈现哪些信息。其名称中的“Meta-”表示它是一个用于优化 harness 的 harness。
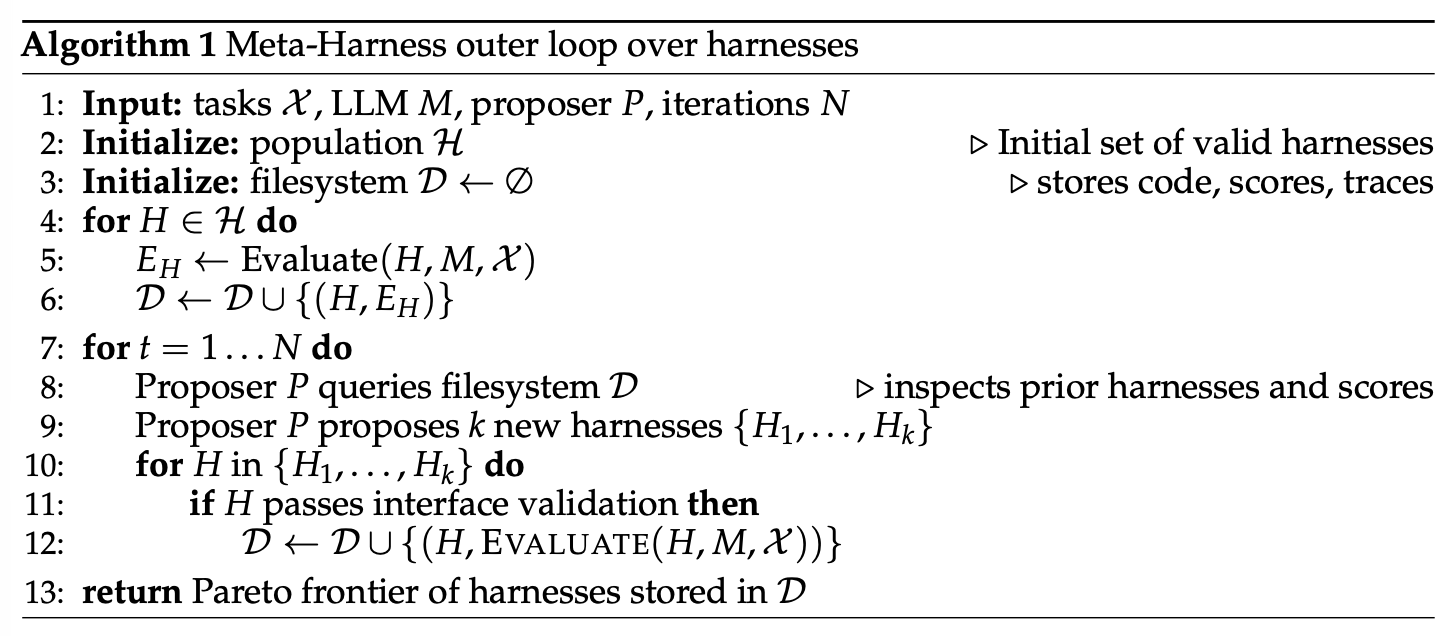
The proposer for creating a new harness is itself a coding agent and the final output is a collection of harness candidates on the Pareto frontier.
用于创建新 harness 的提议器本身就是一个编程智能体,最终输出是帕累托前沿上的一组候选 harness。
grep or cat to read through it instead of shoveling everything into a single prompt context.grep 或 cat 之类的命令来通读执行历史,而不是将所有内容都塞进单个提示词上下文中。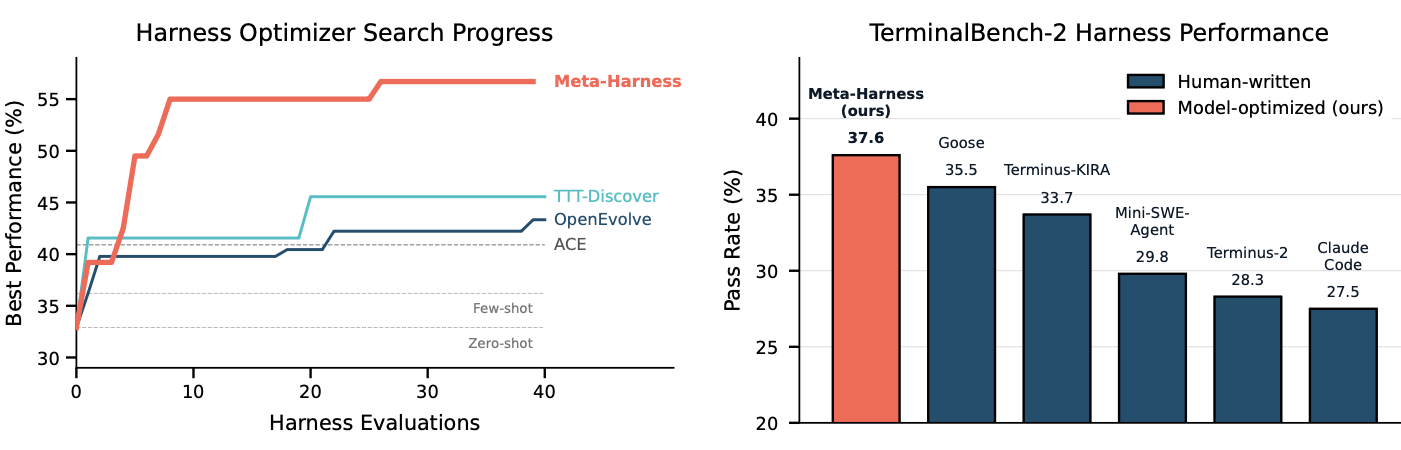
Still, the important lesson is clear: once harness design becomes an executable search space, a strong coding agent can exploit the same design space human engineers use.
不过,重要的启示很明确:一旦 harness 设计成为可执行的搜索空间,强大的编程智能体就能利用与人类工程师相同的设计空间。
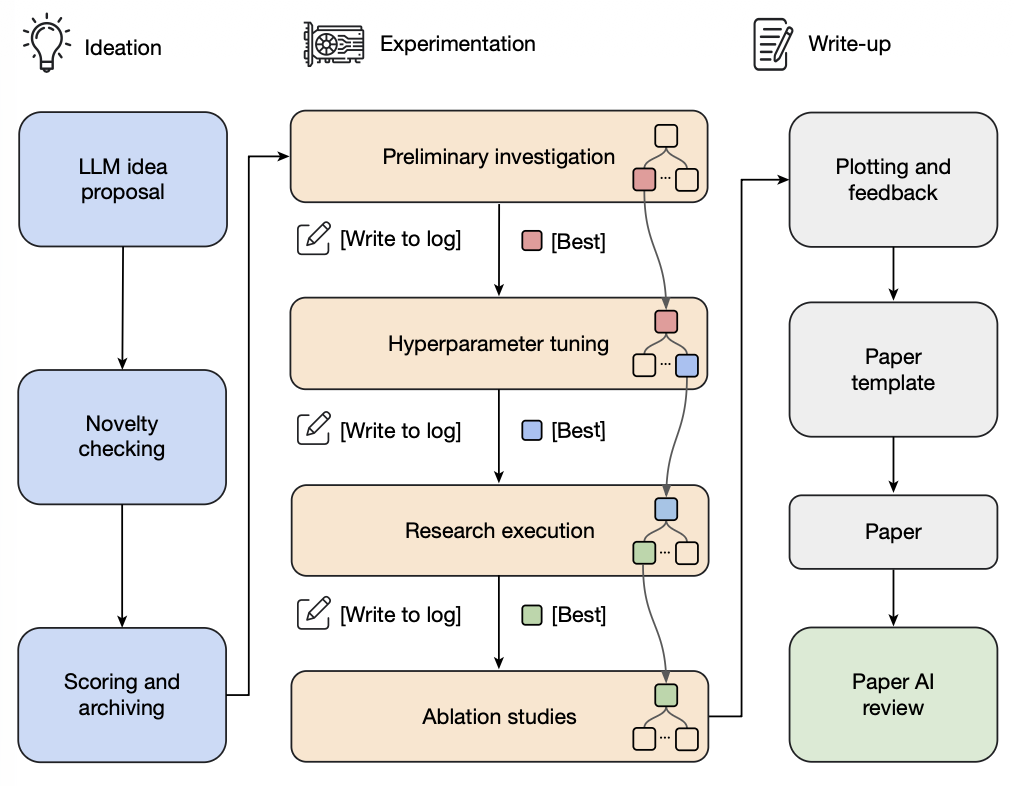
Workflow design in harness engineering can be handcrafted by domain experts. Taking auto-research as an example, various frameworks have been proposed and tested. The AI Scientist system (Lu et al. 2026) builds a pipeline to propose research ideas, write code, run experiments, analyze results, write a manuscript, and perform peer review. Meng et al. (2026) make verifiability the central design constraint in ScientistOne, where every claim (citation, numerical, methodological, conclusion) must trace to an evidence source and is audited by Chain-of-Evidence checks.
harness 工程中的工作流设计可以由领域专家手工完成。以自动化研究为例,人们已经提出并测试了多种框架。AI Scientist 系统(Lu et al. 2026)构建了一条流水线,用于提出研究想法、编写代码、运行实验、分析结果、撰写论文和进行同行评审。Meng et al. (2026) 将可验证性作为核心设计约束,应用于 ScientistOne,其中每一项主张(引用、数值、方法、结论)都必须可追溯到证据来源,并接受 Chain-of-Evidence 检查的审计。
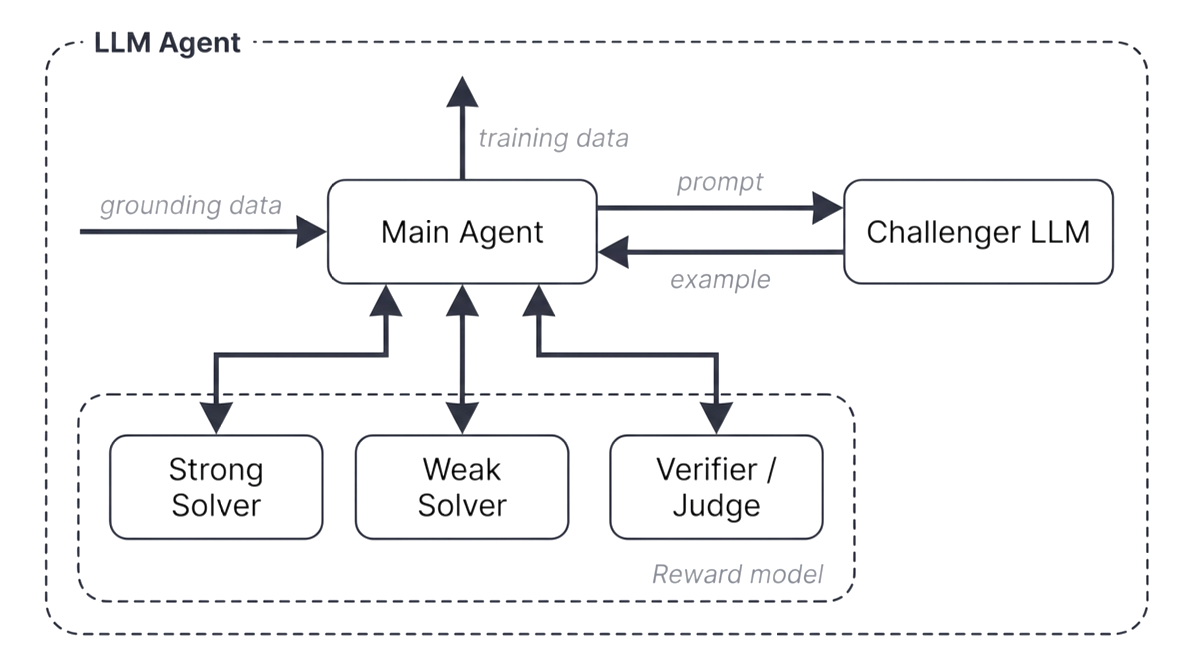
The Autodata agent (Kulikov et al. 2026) is designed to work as a data scientist for generating training and evaluation data. The main agent manages a challenger that proposes problems, a weak solver, a strong solver, and a verifier/judge, aiming to synthesize data at the “just right” level of difficulty, meaning that the strong solver succeeds but the weak solver fails.
该 Autodata 智能体(Kulikov et al. 2026)旨在充当数据科学家,生成训练和评测数据。主智能体管理着一个挑战者,负责提出问题,以及一个弱求解器、一个强求解器和一个验证器/裁判,目标是合成难度“恰到好处”的数据,即强求解器能够成功求解,而弱求解器无法求解。
In Autodata, the challenger prompt is updated iteratively according to feedback from the solvers and verifier. The limitation here is that synthesized tasks are used to fine-tune weak solvers but not strong solvers; if the loop cannot iteratively improve the strong model, it is more like indirect distillation over a generated prompt distribution, with less RSI flavor.
在 Autodata 中,挑战者的提示词会根据求解器和验证器的反馈迭代更新。这里的局限在于,合成任务用于微调弱求解器,而非强求解器;如果这一循环无法迭代改进强模型,那么它就更像是在生成的提示词分布上进行间接蒸馏,RSI 的意味则较弱。
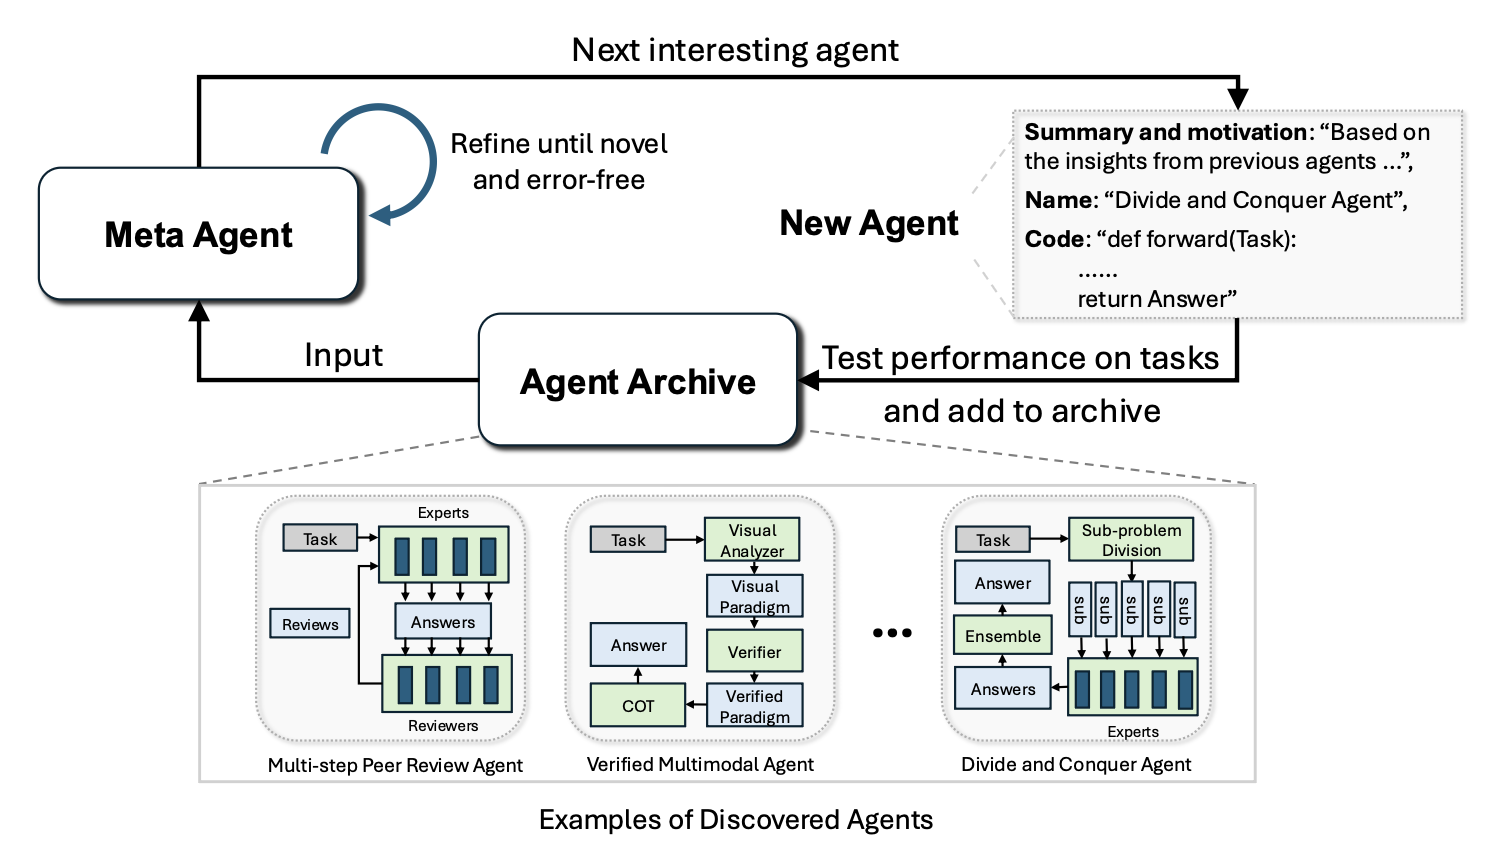
The design space for workflow is enormous, and naturally we can think of workflow design as a search problem, and therefore we should be able to find good solutions by algorithms rather than only manually craft them. Following this direction, Automated Design of Agentic Systems (ADAS; Hu et al. 2025) formulates agent design itself as an optimization problem, “meta-agent search” where a meta-agent proposes new designs of agentic workflows.
工作流的设计空间极其庞大,因此,我们自然可以将工作流设计视为一个搜索问题,也就应该能够通过算法找到好的解决方案,而不只是手动构建。沿着这一方向,智能体系统自动化设计(ADAS;Hu et al. 2025)将智能体设计本身表述为一个优化问题,即“元智能体搜索”,其中由元智能体提出新的智能体工作流设计。
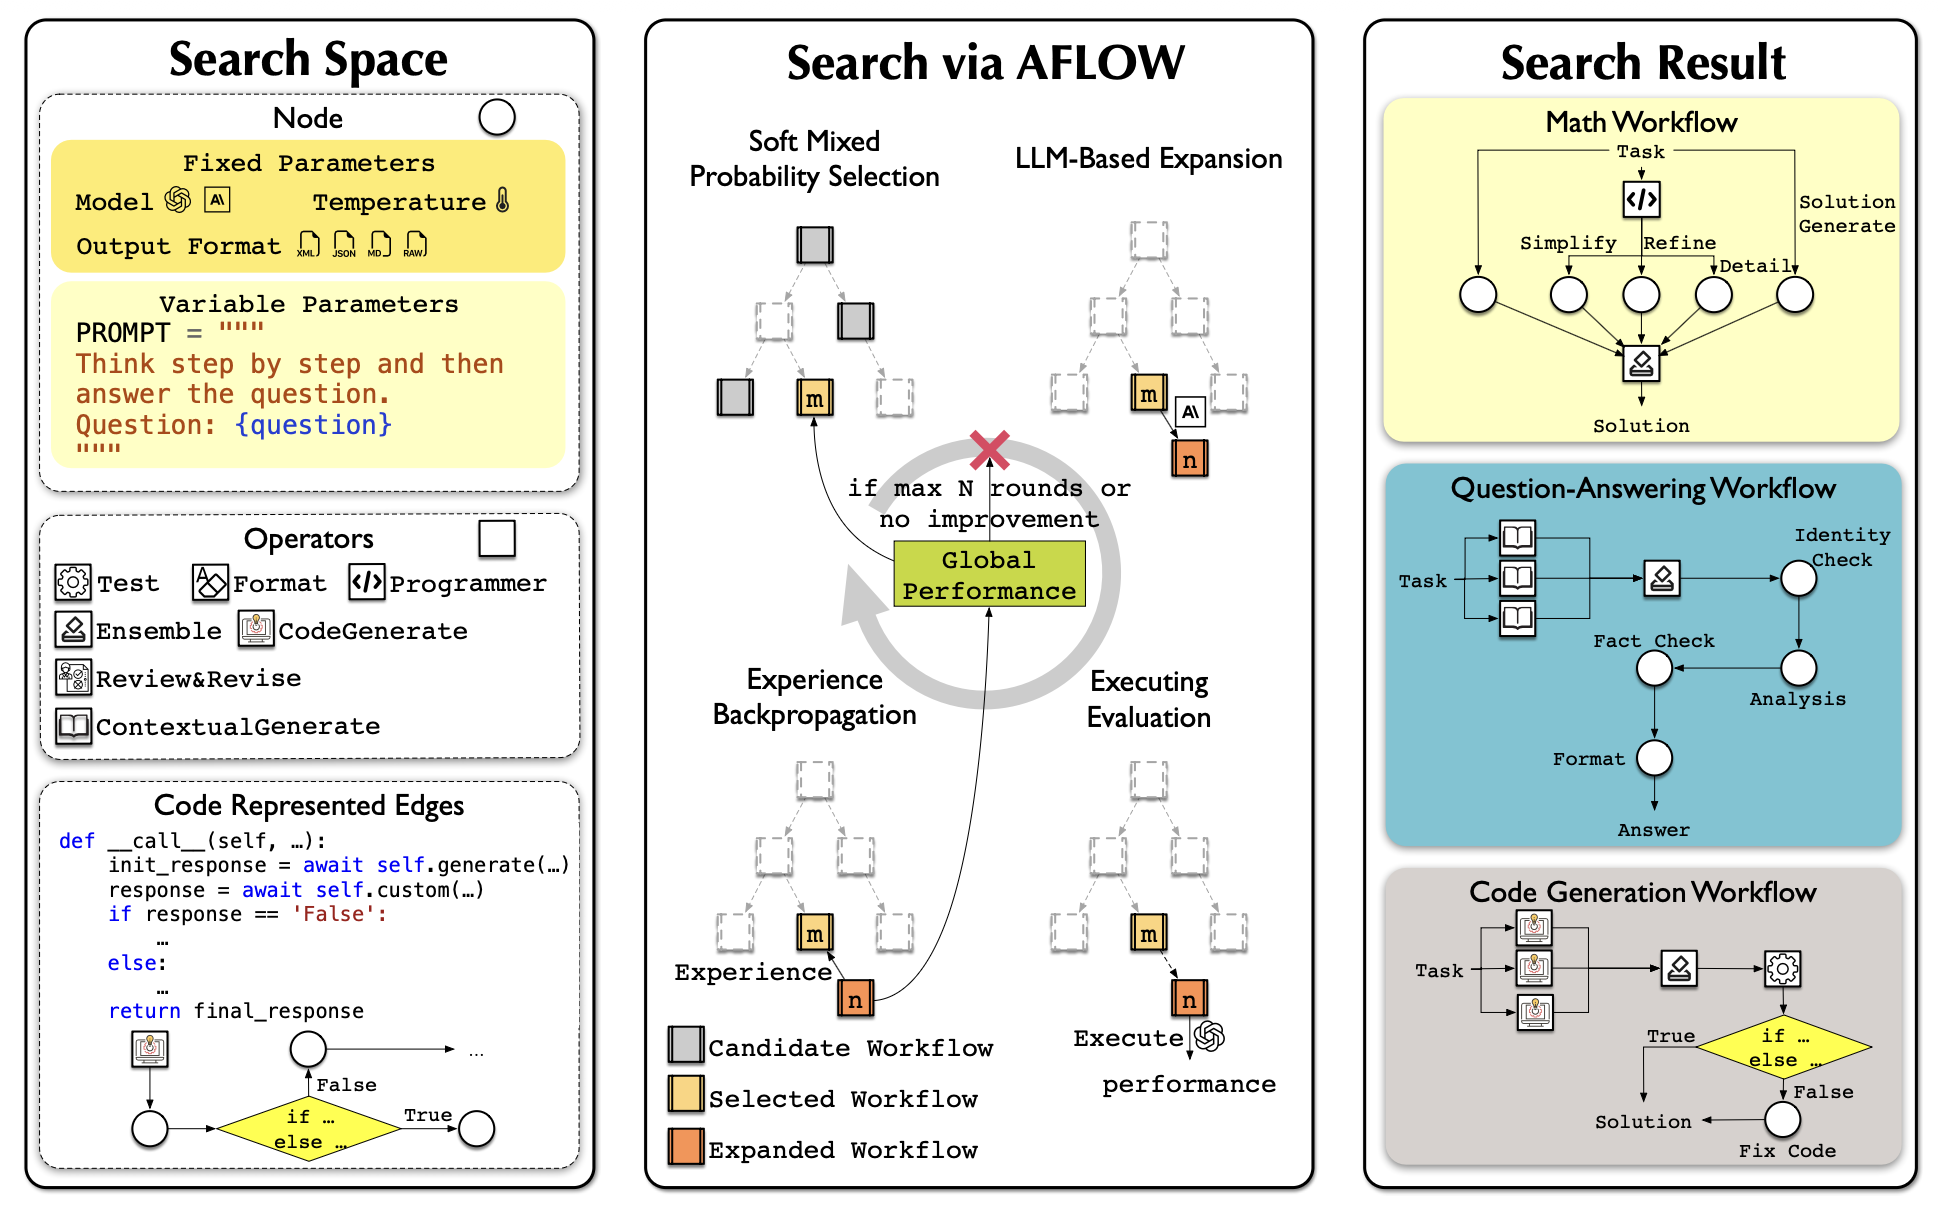
AFlow (Zhang et al. 2025) represents an agentic workflow as a graph, where nodes represent LLM-invoking actions and edges implement logical operations in code. The workflow optimization relies on MCTS (Monte Carlo Tree Search):
AFlow (Zhang et al. 2025)将智能体工作流表示为图,其中节点表示调用 LLM 的动作,边则通过代码实现逻辑运算。工作流优化依赖于 MCTS(蒙特卡洛树搜索):
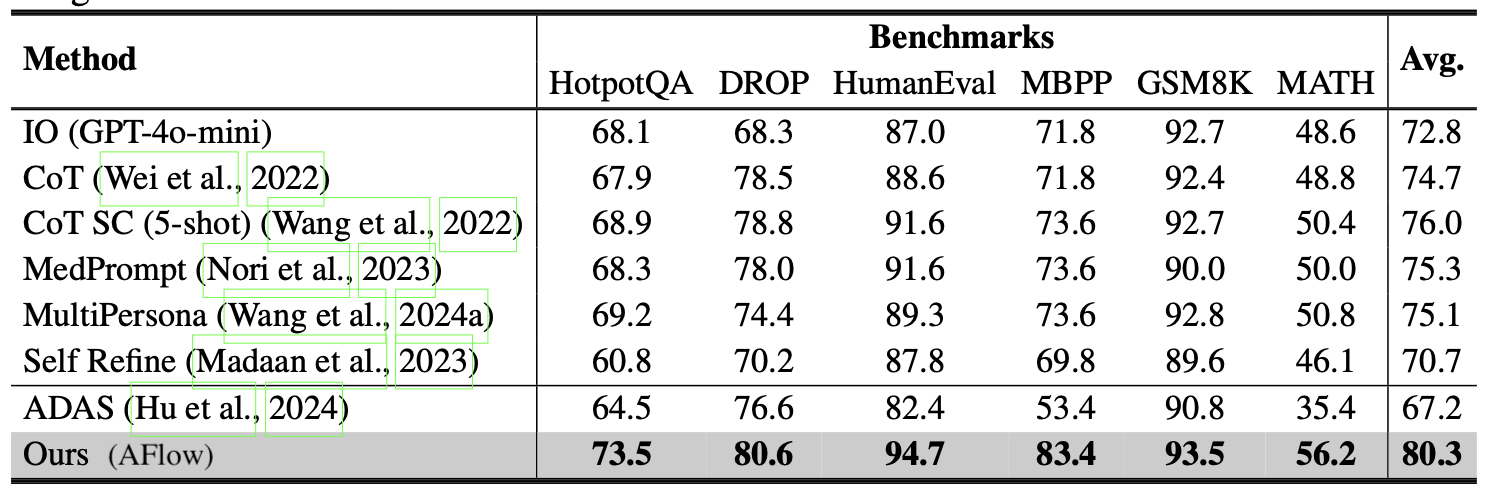
Experiments of AFlow in QA, code, and math tasks showed decent improvement of AFlow over manually designed workflows and ADAS.
AFlow 在问答、代码和数学任务上的实验表明,相较于人工设计的工作流和 ADAS,AFlow 取得了不错的提升。
Either context engineering or workflow design is only one part of a harness. We need to search through the entire design space and optimize context-management logic, workflow, permissions, and many other harness components together. As we have seen in work like Meta-Harness, ADAS, and AFlow, ✨code✨ is a universal language for defining programs and systems. In simple words, a harness is code that programs how prompts, tool calls, subagents, control flow, memory, and workflow logic work together. If an LLM can optimize the code that executes agents, it can access a much larger design space than hand-written prompts.
无论是上下文工程还是工作流设计,都只是运行框架的一部分。我们需要搜索整个设计空间,并共同优化上下文管理逻辑、工作流、权限以及许多其他运行框架组件。正如我们在 Meta-Harness、ADAS 和 AFlow 等工作中所看到的,✨代码✨是一种通用语言,用于定义程序和系统。简单来说,运行框架就是通过编程规定提示词、工具调用、子智能体、控制流、记忆和工作流逻辑如何协同运作的代码。如果 LLM 能够优化执行智能体的代码,它就能探索一个大得多的设计空间,而不局限于手写提示词。
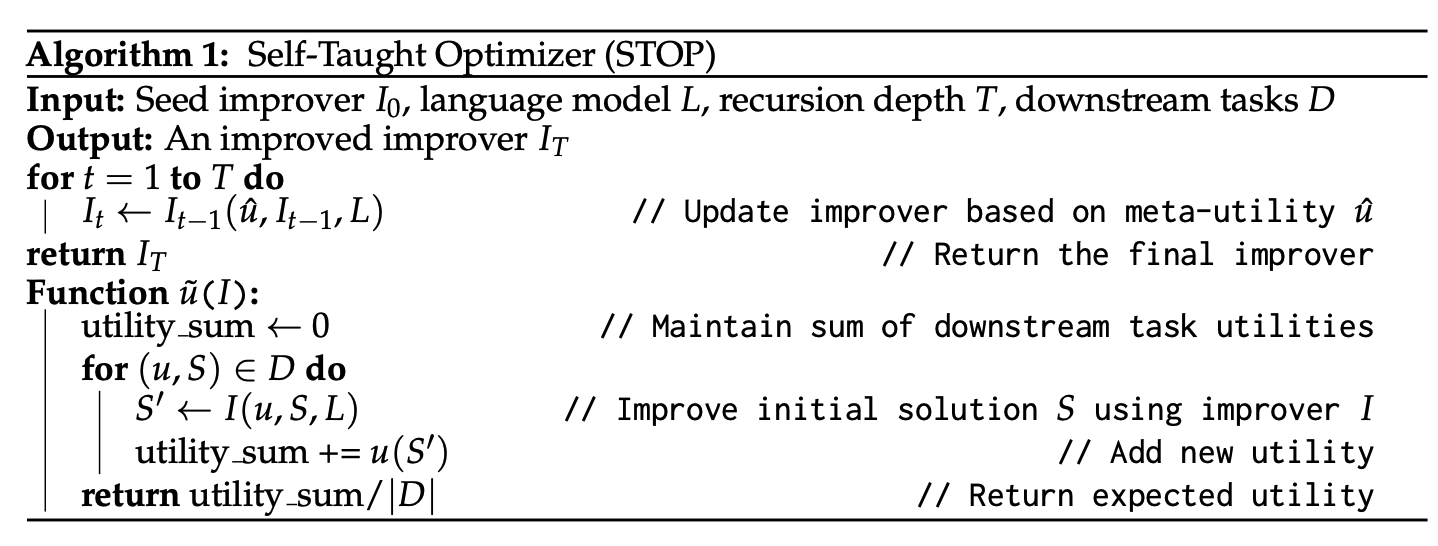
Self-Taught Optimizer (STOP; Zelikman et al. 2023) is one of the early examples of recursive scaffolding improvement. A seed improver at step takes an initial solution , a utility function , and a black-box language model , and returns an improved solution , that is, . The goal of STOP is not directly to improve but to improve the improver itself.
自学优化器(STOP;Zelikman et al. 2023)是递归改进支撑框架的早期实例之一。在步骤 ,种子改进器 接收初始解 、效用函数 和黑盒语言模型 ,并返回改进后的解 ,即 。STOP 的目标不是直接改进 ,而是改进改进器 本身.
First, let’s define the meta-utility as the average utility of a given improver function over a collection of downstream tasks :
首先,我们将元效用定义为给定改进器函数 在一组下游任务 上的平均效用:
Because improving the improver function is an optimization problem itself, we can recursively get a new version of based on ’s performance measured by meta-utility via a self-improvement update:
由于改进改进器函数本身就是一个优化问题,我们可以根据元效用衡量的 的表现,通过自我改进更新递归地得到新版本 :
In their experiments, the improved improver discovered various strategies, such as genetic algorithms, decomposing and improving parts, multi-armed prompt bandits, simulated annealing, varying temperature, and beam/tree search. This is analogous to how a harness workflow can be represented as an object for optimization.
在他们的实验中,改进后的改进器发现了多种策略,例如遗传算法、分解并改进各部分、多臂提示词老虎机、模拟退火、调整温度以及束搜索/树搜索。这类似于将运行框架的工作流表示为优化对象的做法。
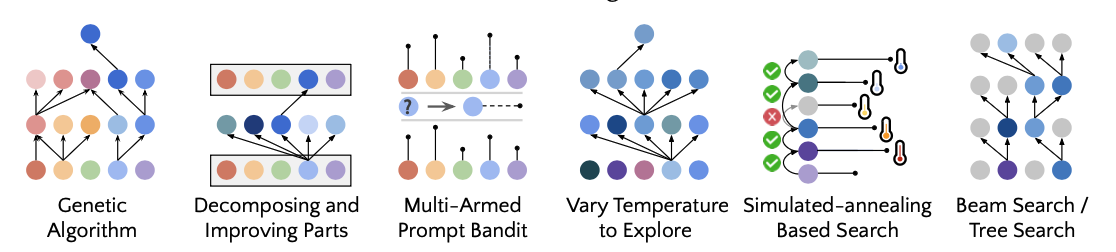
A cautionary result in Zelikman et al. (2023)’s findings is that STOP improved mean downstream performance across iterations with GPT-4 but degraded with weaker models like GPT-3.5 and Mixtral. Recursive structure alone is not enough. The base model must be capable enough to improve the mechanism. This implies that harness improvement enables better deployment of the model but intelligence is still the core.
一个值得警惕的的结果是,Zelikman 等(2023)发现,使用 GPT-4 时,STOP 在多轮迭代中提高了平均下游性能,但使用 GPT-3.5 和 Mixtral 等较弱模型时,性能反而下降。仅有递归结构还不够。基础模型必须具备足够的能力才能改进这一机制。这意味着,改进运行框架能够让模型得到更好的部署,但智能仍然是核心。
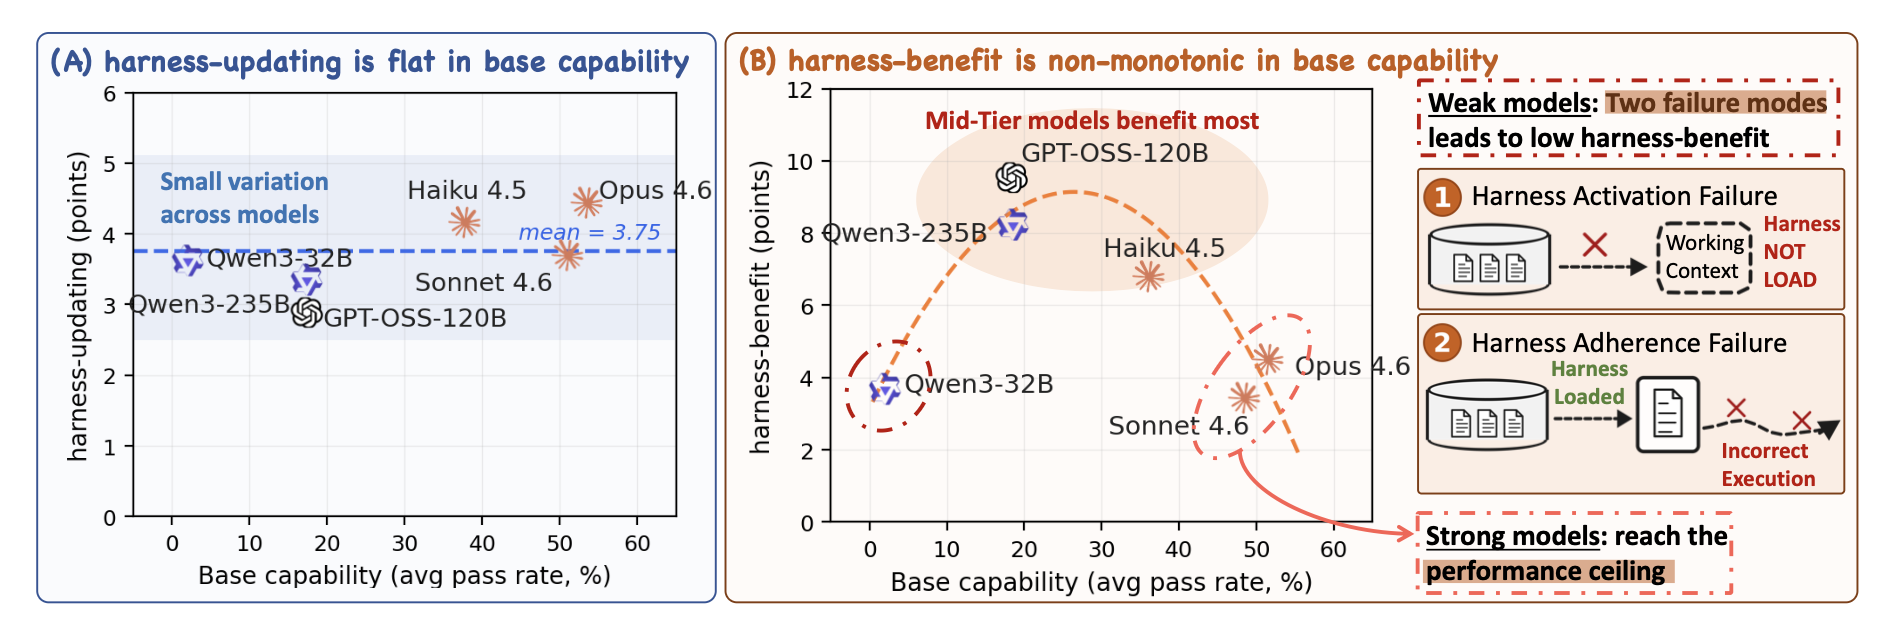
Lin et al. (2026) investigated the dependency of harness evolution on model capabilities in more details. They disentangled two axes: (1) harness-updating refers to the capability of producing useful harness edits and (2) harness-benefit denotes the capability of utilizing the updated harness, to achieve better task solving. Interestingly a range of model of different sizes and core intelligence, from Qwen3.5-9B to Claude Opus 4.6, were observed in their experiments to show similar harness updating capability; the 9B harness proposer/evolver is able to write a skill procedurally isomorphic to Opus. To best utilize a harness, a model needs to invoke skills/tools correctly and timely and be good at long-horizon instruction following.
Lin 等(2026)更详细地研究了运行框架演化对模型能力的依赖。他们区分了两个维度:(1) 运行框架更新能力指生成有用的运行框架修改的能力;(2) 运行框架受益能力指利用更新后的运行框架更好地解决任务的能力。有趣的是,他们在实验中观察到,从 Qwen3.5-9B 到 Claude Opus 4.6,一系列规模和核心智能水平不同的模型表现出相近的运行框架更新能力;9B 的运行框架提案/演化模型能够编写出在流程上与 Opus 所编写的技能同构的技能。要充分利用运行框架,模型需要正确、及时地调用技能/工具,并善于遵循长程指令。
A more recent work, Self-Harness (Zhang et al. 2026), relies on LLM agents to improve their own harness via a propose-evaluate-accept loop.
一项更新的工作,Self-Harness (Zhang 等,2026),依靠 LLM 智能体通过“提出—评测—接受”的循环来改进自身的运行框架。
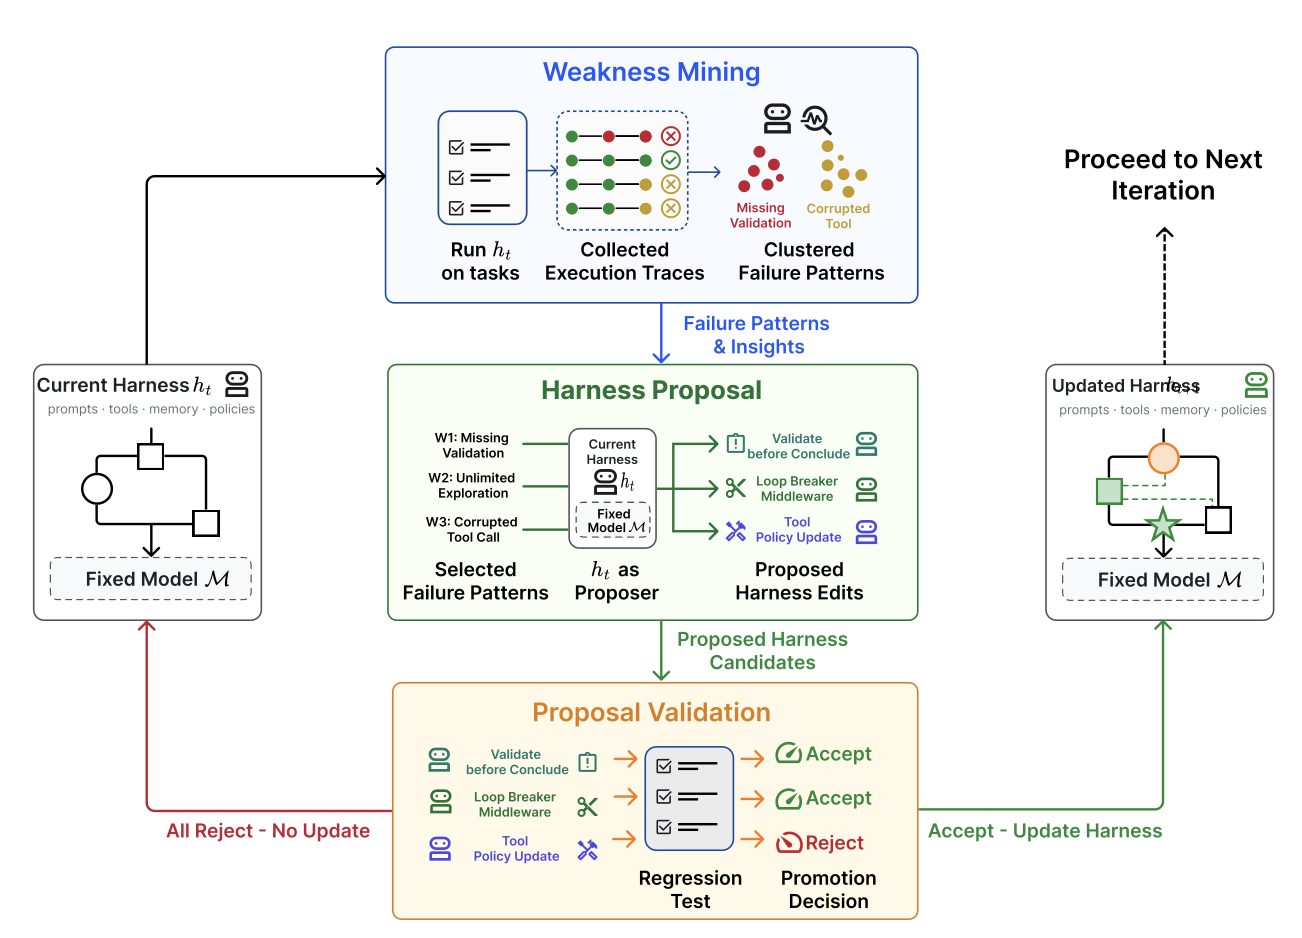
The loop in Self-Harness has three stages:
Self-Harness 的循环分为三个阶段:
When running MiniMax M2.5, Qwen3.5-35B-A3B, and GLM-5 on Terminal-Bench-2, Self-Harness was shown to learn model-specific harness instructions that target at different weaknesses of different base models and improve held-out pass rates.
当运行 MiniMax M2.5, Qwen3.5-35B-A3B 和 GLM-5 进行 Terminal-Bench-2 评测时,结果表明,Self-Harness 能够学习针对特定模型的运行框架指令,针对不同基础模型的不同弱点,并提高留出数据上的通过率。
Self-harness type of work does raise my concerns that if a program is allowed to edit the OS system, abstraction boundaries are broken. The editable surface needs to be properly designed and the permission control and security layers need to live outside this loop. All the challenges around reward hacking still remain.
Self-harness 这类工作确实让我担忧:如果允许程序修改操作系统,抽象边界就会被打破。需要妥善设计可编辑的部分,权限控制和安全层则必须置于这一循环之外。围绕奖励投机的所有挑战仍然存在。
Agentic Harness Engineering (AHE; Lin et al. 2026) see the bottlenecks of harness evolution are around observability—that is, when a rollout fails, we need to know which component is responsible for that and every edit should be grounded by evidence.
智能体运行框架工程(AHE;Lin et al. 2026)认为,运行框架演化的瓶颈在于可观测性——也就是说,当一次展开执行失败时,我们需要知道哪个组件应对此负责,而且每次修改都应以证据为依据。
The framework creates a closed loop with 3 observability pillars:
该框架以 3 个可观测性支柱构建闭环:
On Terminal-Bench-2, AHE achieved better than human-designed harness (OpenCode, Terminus-2, Codex) except for Hard tier and a few other self-evolve baselines (ACE, TF-GRPO). The same frozen harness, without further evolving, transfers to SWE-bench-verified, indicating that the evolved harness is able to encode engineering experience into harness components rather than doing benchmark-specific optimization.
在 Terminal-Bench-2 上,除 Hard 难度档外,AHE 的表现优于人工设计的 harness(OpenCode、Terminus-2、Codex)以及其他几个自演化基线(ACE、TF-GRPO)。同一个冻结后的 harness 无需进一步演化即可迁移至 SWE-bench-verified,这表明演化后的 harness 能将工程经验编码到 harness 组件中,而不是进行针对特定 benchmark 的优化。
Evolutionary search is an optimization method inspired by natural selection (see my old post on evolutionary algorithm). It evolves a population of solutions by mutating them and only keeping those with high “fitness” in the crowd. Evolutionary search comes in handy when (1) the search space is extensive or weirdly shaped; and (2) it is hard to optimize directly with gradients but easy to evaluate solutions. Harness search seems to be a good fit here.
演化搜索是一种受自然选择启发的优化方法(参见我之前关于演化算法的文章)。它通过对解进行变异,并仅保留群体中“适应度”较高的解,使解的种群不断演化。在以下情况下,演化搜索很有用:(1) 搜索空间庞大或形状不规则;且 (2) 难以直接利用梯度进行优化,但容易对解进行评测。Harness 搜索似乎很适合这种方法。
Evolutionary search has been used in prompt engineering in the past studies. Promptbreeder (Fernando et al. 2023) optimizes task-specific prompts through a rich set of mutation operations, and interestingly the mutation prompts (i.e. instructions to an LLM to mutate a task prompt) are themselves also improved through evolution. GEPA (Agrawal et al. 2025) combines reflection-based prompting with evolutionary search and uses natural language reflection over trajectories of trial and error to propose prompt updates.
以往研究已将进化搜索用于提示工程。Promptbreeder (Fernando et al. 2023) 通过丰富的变异操作来优化特定任务的提示,有趣的是,变异提示(即要求 LLM 对任务提示进行变异的指令)本身也通过进化得到改进。GEPA (Agrawal et al. 2025) 将基于反思的提示方法与进化搜索相结合,并对试错轨迹进行自然语言反思,以提出提示更新方案。
Novikov et al. (2025) introduced AlphaEvolve as a coding-agent evolutionary search system, which stores a pool of candidate programs and prompts frozen LLMs to generate diffs for improvement. As the system repeatedly evaluates child programs and keeps successful ones, it discovers better solutions in time.
Novikov et al. (2025) 提出了 AlphaEvolve,这是一个基于编程智能体的进化搜索系统,它维护一个候选程序池,并通过提示让参数冻结的 LLM 生成用于改进的差异补丁。随着系统反复评测子代程序并保留成功的程序,它会逐渐发现更好的解决方案。
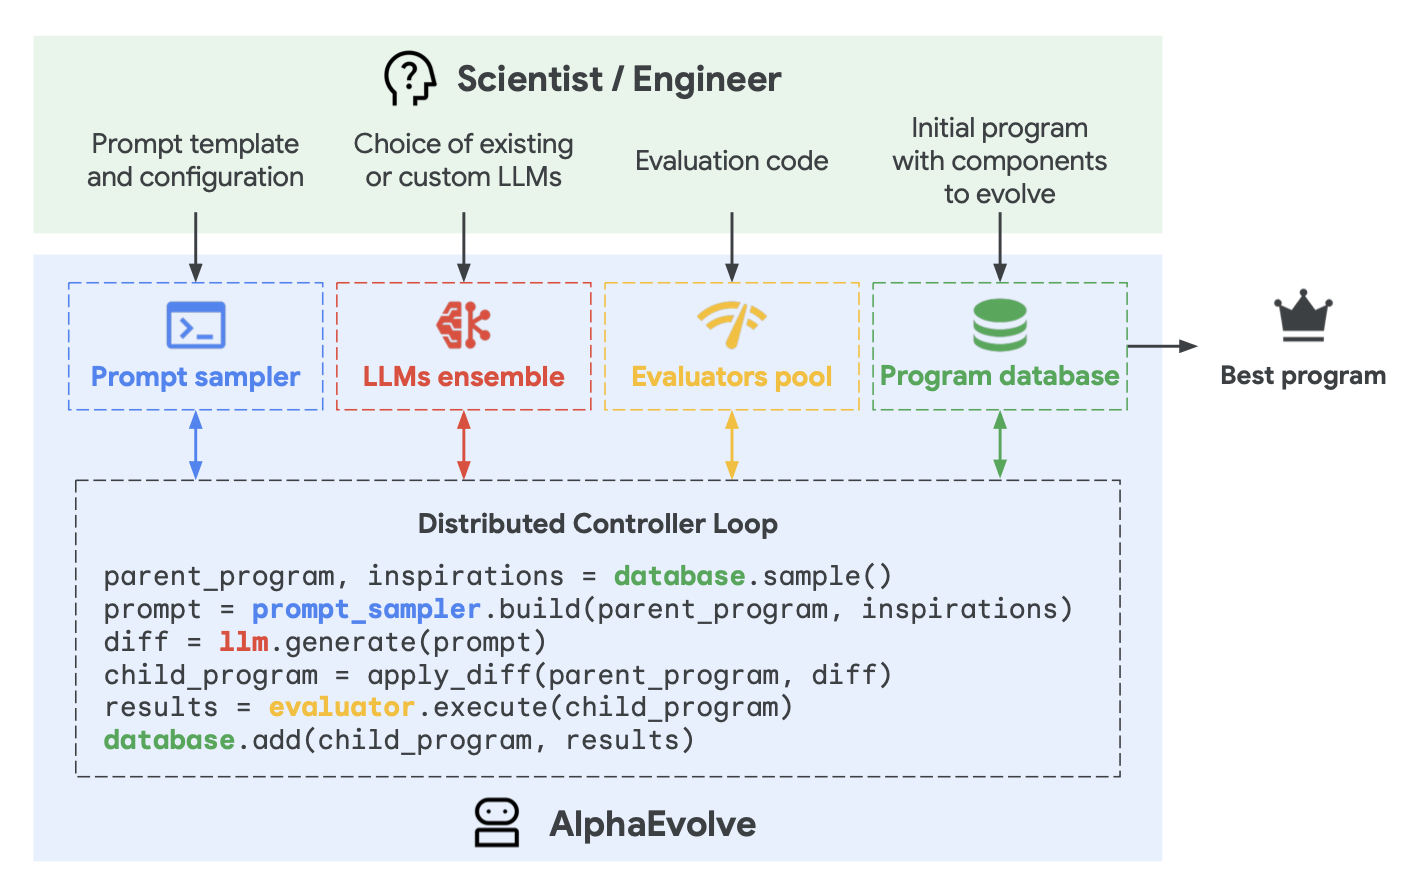
A few details matter in the design of AlphaEvolve:
AlphaEvolve 的设计中有几个重要细节:
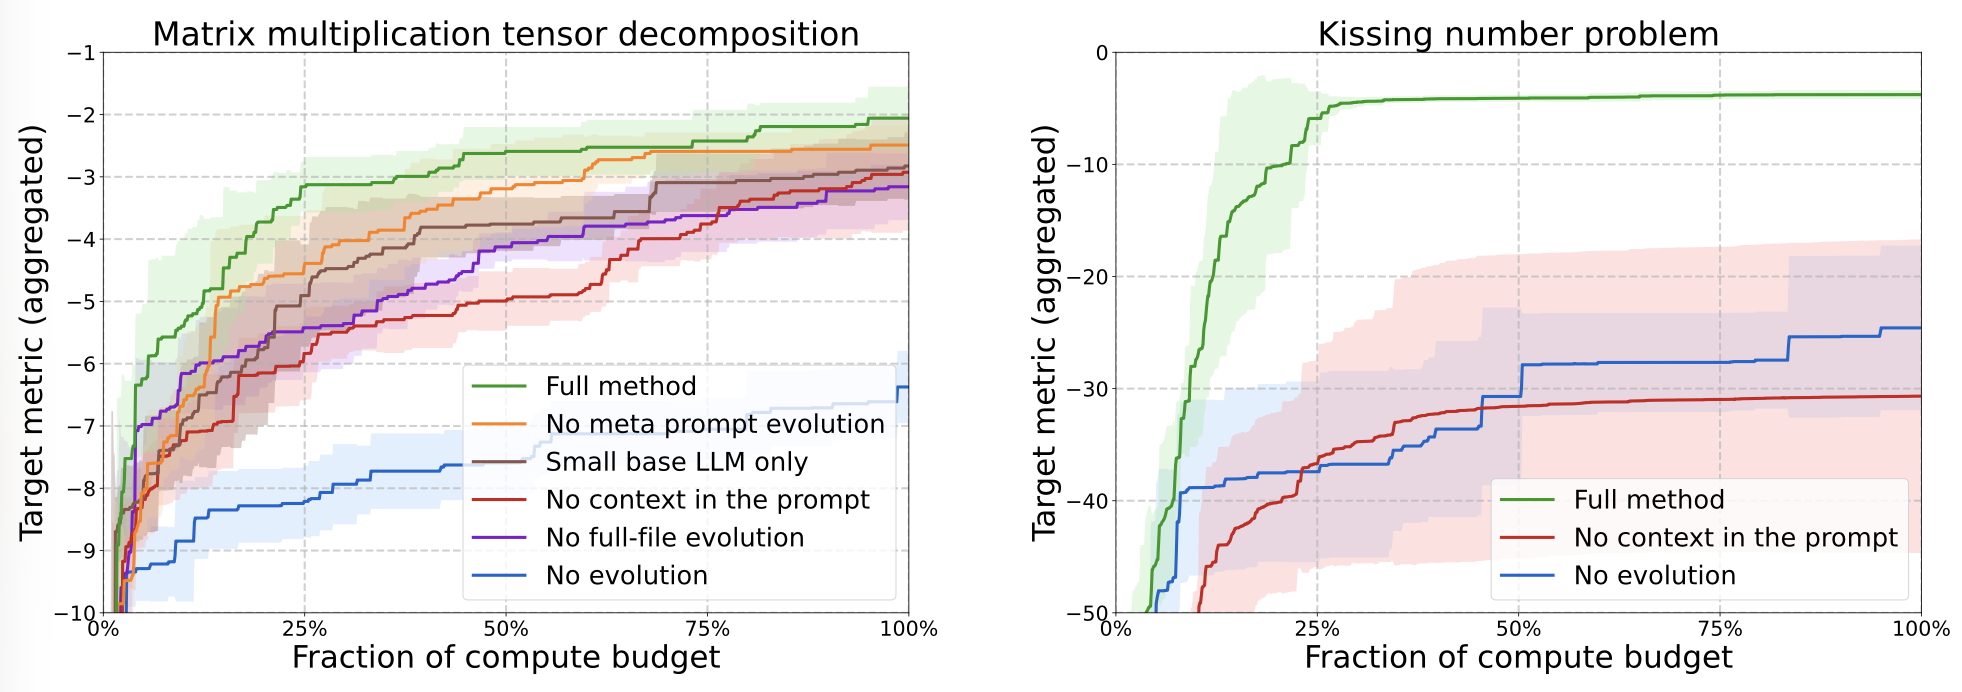
# EVOLVE-BLOCK-START and # EVOLVE-BLOCK-END.# EVOLVE-BLOCK-START 和 # EVOLVE-BLOCK-END.Ablations show the evolution procedure, context in prompts, meta-prompts, full-file evolution and the use of stronger LLMs.
消融实验展示了进化过程、提示中的上下文、元提示、全文件进化以及更强 LLM 的使用。
Recent variants such as ThetaEvolve (Wang et al. 2025) combines evolutionary search with RL and in-context learning, and DemoEvolve (Che, et al. 2026) augments the self-rollout archive with human expert demonstrations as reference experience for harness-level diagnosis and editing. ShinkaEvolve (Lange et al. 2025), on the other hand, introduced three new components to improve LLM sampling efficiency:
近期的变体,例如 ThetaEvolve (Wang et al. 2025) 将进化搜索与 RL 和上下文学习相结合,而 DemoEvolve (Che, et al. 2026) 则将人类专家示范加入自生成轨迹档案,作为执行框架层面诊断和编辑的参考经验。ShinkaEvolve (Lange et al. 2025) 则引入了三个新组件,以提高 LLM 的采样效率:
Unlike the methods above, which focus on solution improvement, Darwin Gödel Machine (DGM; Zhang et al. 2025) explicitly targets the evolution of an editable harness-code repository with an LLM-based coding agent. Precisely, this agent is allowed to modify its own harness. A follow-up work on Hyperagents (Zhang et al. 2026) introduced a meta-agent to control how to modify existing task agents to create new ones.
与上述侧重于改进解决方案的方法不同,Darwin Gödel Machine (DGM; Zhang 等,2025)明确以利用基于 LLM 的编程智能体来演化可编辑的运行框架代码仓库为目标。具体而言,该智能体被允许修改自身的运行框架。关于 Hyperagents 的一项后续研究(Zhang 等,2026)引入了一个元智能体,用于控制如何修改现有任务智能体以创建新的智能体。
<bash_command>) and (2) editor (args: view/create/edit <file_path>).<bash_command>)和 (2) editor(参数:view/create/edit <file_path>).DGM is harness evolution under a fixed model. In experiments with Claude 3.5 Sonnet as the base LLM and simple initial harness configs, the DGM-discovered agents are comparable to or outperform handcrafted agents on SWE-bench Verified (20% to 50%) and Polyglot (14.2% to 30.7%).
DGM 是在模型固定的情况下进行运行框架演化。在以 Claude 3.5 Sonnet 为基础 LLM、采用简单初始运行框架配置的实验中,DGM 发现的智能体在 SWE-bench Verified(20% 至 50%)和 Polyglot(14.2% 至 30.7%)上的表现与手工设计的智能体相当或更优。
This family of methods works well when candidate solutions are automatically evaluable and candidate fitness is easy to quantify, such as matrix multiplication, GPU kernel optimization, algorithm contests, datacenter scheduling. It struggles with domains where evaluation is slow, ambiguous, or mostly heuristic-based. The compute efficiency and effectiveness of evolution are also concerns.
当候选解可以自动评测且候选解的适应度易于量化时,这类方法表现良好,例如矩阵乘法、GPU 内核优化、算法竞赛和数据中心调度。而在评测缓慢、含义模糊或主要基于启发式方法的领域,这类方法则难以奏效。演化的计算效率和有效性也值得关注。
Harness evolution changes the non-parametric system around the model. To enable full self-improvement, the model can totally be allowed to update its own weights at the same time. The weight update can be implemented via improvements in the model training pipeline or continual learning at test time. The topic of continual learning is worthy of its own post in the future.
运行框架演化改变的是模型外围的非参数化系统。为了实现全面的自我改进,完全可以允许模型同时更新自身的权重。权重更新可以通过改进模型训练流水线或在测试时进行持续学习来实现。持续学习这一主题值得在未来单独撰文讨论。
SIA (Hebbar et al. 2026) is an early attempt to combine harness improvement and model-parameter updates in the same optimization loop, with three components in the design:
SIA (Hebbar 等,2026)是在同一优化循环中结合运行框架改进与模型参数更新的一项早期尝试,其设计包含三个组件:
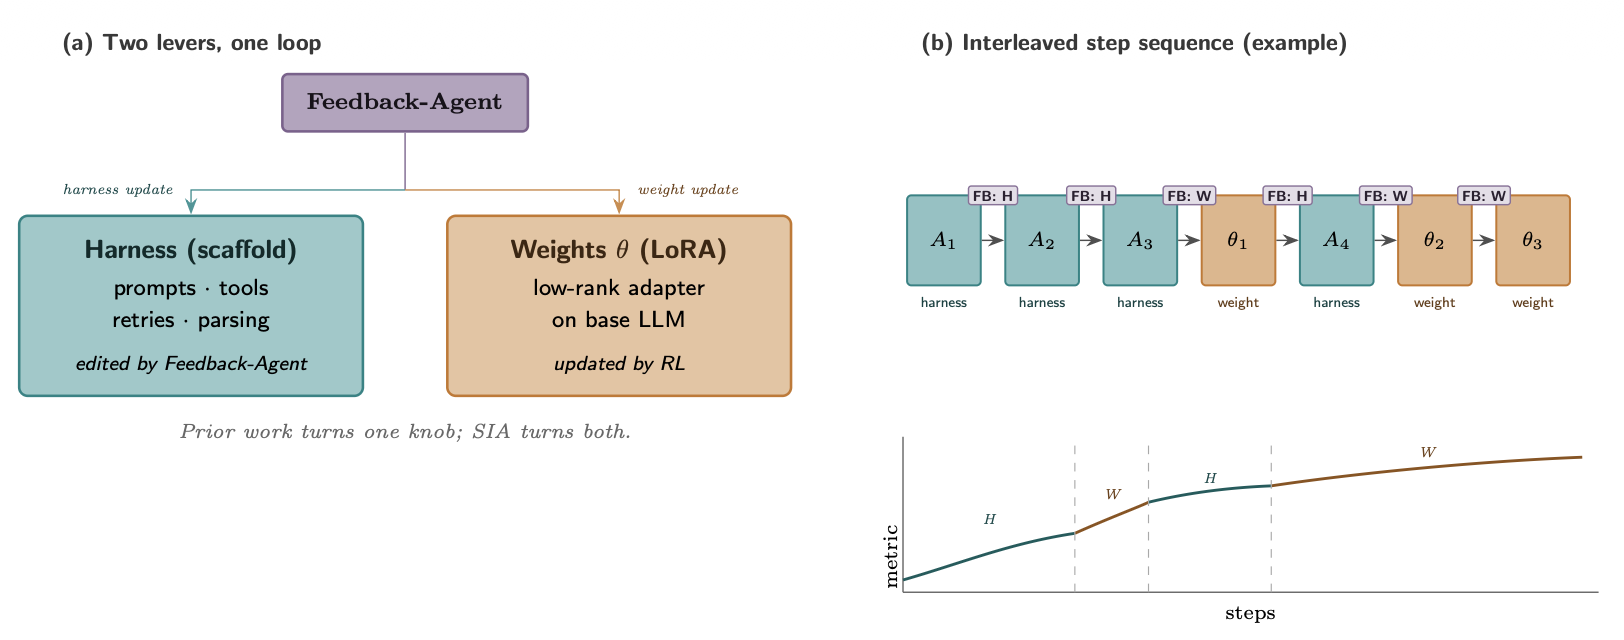
There are a few confounding choices in SIA’s experiments that make the results hard to interpret. For example, the task-specific agent is much weaker than the models used for the Meta-Agent and Feedback-Agent (gpt-oss-120b vs Claude Sonnet 4.6), and the baselines are too weak to cross-reference cleanly against related methods. I would consider the direction interesting, but the evidence provisional. Yet many challenges, such as training stability and Goodhart effect, still remain open.
SIA 实验中的一些设计选择引入了混杂因素,使结果难以解读。例如,任务专用智能体远弱于元智能体和反馈智能体所使用的模型(gpt-oss-120b 对比 Claude Sonnet 4.6),而且基线太弱,难以与相关方法进行清晰的交叉比较。我认为这个方向很有趣,但证据仍属初步。不过,训练稳定性和 Goodhart 效应等诸多挑战仍未解决。
Continual Harness (Karten et al. 2026) experimented in long-horizon gameplay setting with harness updating and co-learning a policy model by distilling a strong teacher model’s labels on low-reward trajectories.
Continual Harness (Karten 等,2026)在长时程游戏场景中开展了实验,更新 harness,并通过蒸馏强教师模型对低奖励轨迹给出的标签,协同学习策略模型。
The AI Scientist line of work is a strong demonstration that an expert-designed harness can coordinate a large portion of auto-research loop, experimented in the form of writing research papers. But paper production is not identical to scientific discovery. A system can write a plausible manuscript while still having fabricated citations, implementation drift, or weak experimental results.
AI Scientist 系列工作以撰写研究论文的形式开展实验,有力地展示了专家设计的 harness 能够协调自动化研究循环中的大部分环节。但产出论文并不等同于科学发现。系统可以写出看似可信的稿件,却仍然存在伪造引用、实现偏移或实验结果薄弱等问题。
Trehan & Chopra (2026) tested whether LLMs can go from a research idea to a paper with minimal scaffolding and basic tools (i.e., read_file, write_file, llm_search, list_files). Each idea had a dedicated workspace where agents could generate and read documents as part of context. They experimented in three domains (world models, multi-agent RL, AI safety & alignment), with each domain containing 45-50 high-quality seed documents to inspire new ideas. Only four ideas were selected by human experts to run through the full pipeline, and only one was fully executed into a paper. They observed six recurring failure modes in the experiments:
Trehan 与 Chopra(2026)测试了 LLM 能否仅依靠最少的辅助框架和基本工具(即 read_file, write_file, llm_search, list_files),从一个研究想法推进到一篇论文。每个想法都有一个专用工作区,智能体可以在其中生成和读取文档,将其作为上下文的一部分。他们在三个领域(世界模型、多智能体 RL、AI 安全与对齐)开展了实验,每个领域包含 45-50 份高质量种子文档,用于启发新想法。人类专家仅选出了四个想法来运行完整流程,其中只有一个完整执行并形成了论文。他们在实验中观察到了六种反复出现的失败模式:
Toward full RSI, researchers have made real progress, but several bottlenecks remain.
在迈向完整 RSI 的过程中,研究人员已取得切实进展,但仍存在若干瓶颈。
1. Weak and fuzzy evaluators. Many research claims do not have a fast and precise verifier, and the same is true for many real-world tasks. Current self-improvement loops work best for tasks when evaluation metrics are measurable and objective, similar as how RL works.
1. 能力薄弱且标准模糊的评测器。许多研究论断没有快速且精确的验证器,许多现实世界的任务也是如此。当前的自我改进循环在评测指标可衡量且客观的任务上效果最好,这类似于RL 的工作原理.
Research taste, novelty, and long-term scientific value are much harder to measure. For example, research taste often mixes problem framing, experimental design, and judgment about which surprising results are worth pursuing and which failure cases are worth retries.
研究品味、新颖性和长期科学价值则难以衡量得多。例如,研究品味往往综合了问题构建、实验设计,以及对哪些意外结果值得继续探索、哪些失败案例值得重试的判断。
2. Context and memory lifecycle. Memory grows as AI agents become more autonomous and independent. A useful harness needs to manage context and memory to complement existing limitation in long-context generation while still maximizing the success of long-horizon tasks. Since humans are able to maintain memory through our life time, I see an anoloy here that context engineering will and should become a core part of intelligence, rather than staying in the software system layer.
2. 上下文与记忆的生命周期。随着 AI 智能体变得更加自主和独立,记忆也会不断增长。一个实用的运行框架需要管理上下文和记忆,以弥补长上下文生成现有的局限,同时仍尽可能提高长程任务的成功率。由于人类能够在一生中维持记忆,我认为这里存在一个类比:上下文工程将会且应当成为智能的核心组成部分,而不是停留在软件系统层。
3. Negative results. Researchers are incentivized to publish successful results and thus literature is biased toward successes. LLMs trained on a vast amount of data (mostly human created, at least for now, lol) may be bad at deciding when to abandon a hypothesis, report a negative result, or even acknowledge a failure due to the imablance of success vs failure cases in data. A research harness should make failed attempts easy to preserve, as learning from failure is the best way to trim down the task search space.
3. 阴性结果。研究人员受到发表成功结果的激励,因此文献偏向成功案例。在海量数据上训练的 LLM(这些数据大多由人类创建,至少目前如此,哈哈)可能不善于判断何时应放弃一个假设、报告阴性结果,甚至承认失败,因为数据中的成功与失败案例并不均衡。研究运行框架应当让失败尝试易于保存,因为从失败中学习是缩小任务搜索空间的最佳方式。
4. Diversity collapse. Evolutionary and RL loops tend to exploit known high-reward patterns. We need mechanisms to prevent the population from collapsing into variants of the same solution. This is especially critical for open-ended research, where the best path may initially look worse under the current evaluator.
4. 多样性坍缩。进化和 RL 循环往往倾向于利用已知的高奖励模式。我们需要一些机制来防止种群坍缩为同一解决方案的各种变体。这对于开放式研究尤为关键,因为在当前评测器下,最佳路径起初可能看起来更差。
5. Reward hacking. A self-improvement loop optimizes whatever signal it is given. If the reward comes from unit tests, the agent may overfit to tests; if it comes from a judge model, it may learn reward hacking tricks specific to this judge; if it comes from benchmark scores, it may exploit benchmark artifacts.
5. 奖励投机.自我改进循环会优化任何给定的信号。如果奖励来自单元测试,智能体可能会对测试过拟合;如果奖励来自裁判模型,它可能会学会针对该裁判的奖励投机技巧;如果奖励来自 benchmark 分数,它可能会利用 benchmark 中的人为痕迹。
The evaluator and permission control should likely sit outside the loop that evolves harness, with held-out tests, trace audits, and human review at decision points that matter—how much oversight can be scaled up and automated remains an open research area.
评测器和权限控制很可能应当置于演化运行框架的循环之外,并在重要决策节点采用留出测试、轨迹审计和人工审核——监督能在多大程度上扩展规模并实现自动化,仍是一个开放的研究领域。
6. Long-term success. An extrinsic loop of optimization works on rewards outside of individual rollouts that we can simulate in training sandbox.
6. 长期成功。外层优化循环针对的是超出我们能够在训练沙箱中模拟的单次 rollout 范围的奖励。
Take coding agent as an example. Coding agents have already increased daily productivity in software engineering, but many optimization goals are still too short-term. It can often complete the task at hand, but less obvious how it should protect the long-term health of a repo collectively maintained by hundreds or thousands of engineers. Standard sandbox-based RLVR-style training rarely captures maintainability, ownership boundaries, migration cost, backwards compatibility, or future debugging burden.
以编程智能体为例。编程智能体已经提高了软件工程的日常生产力,但许多优化目标仍然过于短期化。它通常能够完成手头的任务,但对于一个由数百或数千名工程师共同维护的代码仓库,它应如何保障其长期健康,则不那么明确。标准的基于沙箱的 RLVR 式训练很少涵盖可维护性、归属边界、迁移成本、向后兼容性或未来的调试负担。
7. The role of humans. Humans should move up the stack, not be removed from the loop, meaning that human should provide oversight at the right time, at the right abstraction level and our system design should consider when and how to set up such touch points.
7. 人类的作用。人类应向技术栈的更高层移动,而不是被移出闭环;这意味着人类应在恰当的时机、恰当的抽象层级提供监督,而我们的系统设计应考虑何时以及如何设置这些交互节点。
Many challenges listed above need human’s feedback and steering. After all, we are building the technology for better future of humanity, not other way around.
上述许多挑战都需要人类的反馈和引导。毕竟,我们开发技术是为了让人类拥有更美好的未来,而不是反过来。
Please cite this work as:
请按以下格式引用本作品:
Weng, Lilian. “Harness Engineering for Self-Improvement”. Lil’Log (Jul 2026). https://lilianweng.github.io/posts/2026-07-04-harness/
Weng, Lilian. “用于自我改进的 Harness 工程”. Lil’Log(2026 年 7 月). https://lilianweng.github.io/posts/2026-07-04-harness/
Or use the BibTeX citation:
或使用 BibTeX 引用:
@article{weng2026harness,
  title = {Harness Engineering for Self-Improvement},
  author = {Weng, Lilian},
  journal = {lilianweng.github.io},
  year = {2026},
  month = {July},
  url = "https://lilianweng.github.io/posts/2026-07-04-harness/"
}
@article{weng2026harness,
  title = {Harness Engineering for Self-Improvement},
  author = {Weng, Lilian},
  journal = {lilianweng.github.io},
  year = {2026},
  month = {July},
  url = "https://lilianweng.github.io/posts/2026-07-04-harness/"
}
Claude 3.5 Sonnet, ~21%) does not outperform ML PhDs.GPT-4o and GPT-4o-mini) achieved only 21% accuracy on the hardest task.o1-preview with AIDE scaffolding, reached at least Kaggle bronze-medal level in 16.9% of competitions.Claude 3.5 Sonnet,约 21%)并未超越机器学习博士。GPT-4o和GPT-4o-mini)在最难的任务上仅达到 21% 的准确率。o1-preview 搭配 AIDE 框架,在 16.9% 的竞赛中至少达到了 Kaggle 铜牌水平。[1] Good, I. J. “Speculations Concerning the First Ultraintelligent Machine.” Advances in Computers, 6:31–88, 1965.
[1] Good, I. J. 《关于第一台超智能机器的推测》。 Advances in Computers, 6:31–88, 1965.
[2] Yudkowsky, Eliezer. “Recursive Self-Improvement.” LessWrong, 2008.
[2] Yudkowsky, Eliezer. 《递归自我改进》。 LessWrong, 2008.
[3] Choi, et al. “Anchored Self-Play for Code Repair.” ICML 2026.
[3] Choi 等。《用于代码修复的锚定自博弈》。 ICML 2026.
[4] Zhao, et al. “Absolute Zero: Reinforced Self-play Reasoning with Zero Data.” arXiv preprint arXiv:2505.03335, 2025.
[4] Zhao 等。《Absolute Zero:零数据的强化自博弈推理》。 arXiv 预印本 arXiv:2505.03335, 2025.
[5] Yuan, et al. “Self-Rewarding Language Models.” arXiv preprint arXiv:2401.10020, 2024.
[5] Yuan 等。《自奖励语言模型》。 arXiv 预印本 arXiv:2401.10020, 2024.
[6] Chen, et al. “Self-Play Fine-Tuning Converts Weak Language Models to Strong Language Models.” ICML 2024.
[6] Chen 等人。“自博弈微调将弱语言模型转变为强语言模型。” ICML 2024。
[7] Zhang, et al. “Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models.” ICLR 2026.
[7] Zhang 等人。“智能体上下文工程:为自我改进的语言模型演化上下文。” ICLR 2026。
[8] Ye, et al. “Meta Context Engineering via Agentic Skill Evolution.” arXiv preprint arXiv:2601.21557, 2026.
[8] Ye 等人。“通过智能体技能演化实现元上下文工程。” arXiv 预印本 arXiv:2601.21557,2026。
[9] Lee, et al. “Meta-Harness: End-to-End Optimization of Model Harnesses.” arXiv preprint arXiv:2603.28052, 2026.
[9] Lee 等人。“Meta-Harness:模型运行框架的端到端优化。” arXiv 预印本 arXiv:2603.28052,2026。
[10] Lu, et al. “Towards end-to-end automation of AI research.” Nature, 651:914–919, 2026.
[10] Lu 等人。“迈向 AI 研究的端到端自动化。” Nature, 651:914–919, 2026.
[11] Meng, et al. “ScientistOne: Towards Human-Level Autonomous Research via Chain-of-Evidence.” arXiv preprint arXiv:2605.26340, 2026.
[11] Meng 等人。“ScientistOne:通过证据链迈向人类水平的自主研究。” arXiv 预印本 arXiv:2605.26340,2026。
[12] Kulikov, et al. “Autodata: An agentic data scientist to create high quality synthetic data.” arXiv preprint arXiv:2606.25996, 2026.
[12] Kulikov 等人。“Autodata:用于创建高质量合成数据的数据科学家智能体。” arXiv 预印本 arXiv:2606.25996,2026。
[13] Hu, Lu, and Clune. “Automated Design of Agentic Systems.” ICLR 2025.
[13] Hu、Lu 和 Clune。“智能体系统的自动化设计。” ICLR 2025。
[14] Madaan, et al. “Self-Refine: Iterative Refinement with Self-Feedback.” NeurIPS 2023.
[14] Madaan 等人。“Self-Refine:利用自我反馈进行迭代改进。” NeurIPS 2023。
[15] Zhang, et al. “AFlow: Automating Agentic Workflow Generation.” ICLR 2025.
[15] Zhang 等人。“AFlow:实现智能体工作流生成的自动化。” ICLR 2025。
[16] Zelikman, et al. “Self-Taught Optimizer (STOP): Recursively Self-Improving Code Generation.” COLM 2024.
[16] Zelikman 等人。“自学优化器(STOP):递归自我改进的代码生成。” COLM 2024。
[17] Zhang, et al. “Self-Harness: Harnesses That Improve Themselves.” arXiv preprint arXiv:2606.09498, 2026.
[17] Zhang 等人。“Self-Harness:能够自我改进的运行框架。” arXiv 预印本 arXiv:2606.09498,2026。
[18] Fernando, et al. “Promptbreeder: Self-Referential Self-Improvement Via Prompt Evolution.” arXiv preprint arXiv:2309.16797, 2023.
[18] Fernando 等人。“Promptbreeder:通过提示演化实现自指式自我改进。” arXiv 预印本 arXiv:2309.16797,2023。
[19] Agrawal, A. et al. “GEPA: Reflective Prompt Evolution Can Outperform Reinforcement Learning.” arXiv preprint arXiv:2507.19457, 2025.
[19] Agrawal, A. 等人。“GEPA:反思式提示演化能够优于强化学习。” arXiv 预印本 arXiv:2507.19457,2025。
[20] Novikov, et al. “AlphaEvolve: A coding agent for scientific and algorithmic discovery.” arXiv preprint arXiv:2506.13131, 2025.
[20] Novikov 等人。“AlphaEvolve:用于科学与算法发现的编程智能体。” arXiv 预印本 arXiv:2506.13131,2025。
[21] Lange, Imajuku, and Cetin. “ShinkaEvolve: Towards Open-Ended And Sample-Efficient Program Evolution.” arXiv preprint arXiv:2509.19349, 2025.
[21] Lange、Imajuku 和 Cetin。“ShinkaEvolve:迈向开放式且样本高效的程序演化。” arXiv 预印本 arXiv:2509.19349,2025。
[22] Wang, et al. “ThetaEvolve: Test-time Learning on Open Problems.” arXiv preprint arXiv:2511.23473, 2025.
[22] Wang 等人。“ThetaEvolve:针对未解问题的测试时学习。” arXiv 预印本 arXiv:2511.23473,2025。
[23] Zhang, et al. “Darwin Gödel Machine: Open-Ended Evolution of Self-Improving Agents.” arXiv preprint arXiv:2505.22954, 2025.
[23] Zhang 等人。“Darwin Gödel Machine:自我改进智能体的开放式演化。” arXiv 预印本 arXiv:2505.22954,2025。
[24] Zhang, et al. “Hyperagents.” arXiv preprint arXiv:2603.19461, 2026.
[24] Zhang 等人。“Hyperagents。” arXiv 预印本 arXiv:2603.19461,2026。
[25] Yuksekgonul, et al. “Learning to Discover at Test Time.” arXiv preprint arXiv:2601.16175, 2026.
[25] Yuksekgonul 等。《学习在测试时进行发现》。 arXiv 预印本 arXiv:2601.16175,2026。
[26] Riaz, et al. “Epistemic Uncertainty for Test-Time Discovery.” arXiv preprint arXiv:2605.11328, 2026.
[26] Riaz 等。《用于测试时发现的认知不确定性》。 arXiv 预印本 arXiv:2605.11328,2026。
[27] Hebbar, et al. “SIA: Self Improving AI with Harness & Weight Updates.” arXiv preprint arXiv:2605.27276, 2026.
[27] Hebbar 等。《SIA:通过运行框架与权重更新实现自我改进的 AI》。 arXiv 预印本 arXiv:2605.27276,2026。
[28] Trehan and Chopra. “Why LLMs Aren’t Scientists Yet: Lessons from Four Autonomous Research Attempts.” arXiv preprint arXiv:2601.03315, 2026.
[28] Trehan 和 Chopra。《为什么 LLM 还不是科学家:四次自主研究尝试的经验教训》。 arXiv 预印本 arXiv:2601.03315,2026。
[29] Bubeck, et al. “Early science acceleration experiments with GPT-5.” arXiv preprint arXiv:2511.16072, 2025.
[29] Bubeck 等。《使用 GPT-5 加速科学研究的早期实验》。 arXiv 预印本 arXiv:2511.16072,2025。
[30] Starace, et al. “PaperBench: Evaluating AI’s Ability to Replicate AI Research.” ICML 2025.
[30] Starace 等。《PaperBench:评测 AI 复现 AI 研究的能力》。 ICML 2025。
[31] Wijk, et al. “RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts.” ICML 2025.
[31] Wijk 等。《RE-Bench:以人类专家为参照评测语言模型智能体的前沿 AI 研发能力》。 ICML 2025。
[32] Chan, et al. “MLE-bench: Evaluating Machine Learning Agents on Machine Learning Engineering.” arXiv preprint arXiv:2410.07095, 2024.
[32] Chan 等。《MLE-bench:评测机器学习智能体的机器学习工程能力》。 arXiv 预印本 arXiv:2410.07095,2024。
[33] Chen, et al. “ScienceAgentBench: Toward Rigorous Assessment of Language Agents for Data-Driven Scientific Discovery.” ICLR 2025.
[33] Chen 等。《ScienceAgentBench:迈向对数据驱动科学发现中语言智能体的严格评估》。 ICLR 2025。
[34] Siegel, et al. “CORE-Bench: Fostering the Credibility of Published Research Through a Computational Reproducibility Agent Benchmark.” TMLR 2024.
[34] Siegel 等。《CORE-Bench:通过计算可复现性智能体 benchmark 提升已发表研究的可信度》。 TMLR 2024。
[35] Ouyang, et al. “KernelBench: Can LLMs Write Efficient GPU Kernels?” arXiv preprint arXiv:2502.10517, 2025.
[35] Ouyang 等。《KernelBench:LLM 能编写高效的 GPU 内核吗?》。 arXiv 预印本 arXiv:2502.10517,2025。
[36] Lin, et al. “Harness Updating Is Not Harness Benefit: Disentangling Evolution Capabilities in Self-Evolving LLM Agents.” arXiv preprint arXiv:2605.30621, 2026.
[36] Lin 等。《运行框架更新不等于运行框架收益:解耦自我演化 LLM 智能体的演化能力》。 arXiv 预印本 arXiv:2605.30621,2026。
[37] Lin, et al. “Agentic Harness Engineering: Observability-Driven Automatic Evolution of Coding-Agent Harnesses.” arXiv preprint arXiv:2604.25850, 2026.
[37] Lin 等。《智能体运行框架工程:可观测性驱动的编程智能体运行框架自动演化》。 arXiv 预印本 arXiv:2604.25850,2026。
[38] Karten, et al. “Continual Harness: Online Adaptation for Self-Improving Foundation Agents.” arXiv preprint arXiv:2605.09998, 2026.
[38] Karten 等。《Continual Harness:面向自我改进基础智能体的在线适应》。 arXiv 预印本 arXiv:2605.09998,2026。
[39] Che, et al. “DemoEvolve: Overcoming Sparse Feedback in Agentic Harness Evolution with Demonstrations.” arXiv preprint arXiv:2605.24539, 2026.
[39] Che 等。《DemoEvolve:利用示范克服智能体运行框架演化中的稀疏反馈问题》。 arXiv 预印本 arXiv:2605.24539,2026。